I’ve spent 20 years building publishing websites, and I’ve advised small businesses on SEO. I care about what an SEO campaign leaves behind. If the deliverable is thousands of interchangeable pages, rented backlinks or a website that shows Google something customers cannot see, the owner inherits all of it. The agency’s contract can end. The work remains attached to your business.
For an established site, I would investigate scaled content abuse, manufactured link networks and cloaking first. They can turn a questionable tactic into a system spread across an entire operation. The rest of the list covers borrowed domain reputation, paid links, doorway pages, fake local listings and reviews, hidden content, misleading markup, and other shortcuts worth recognising. Each entry explains the warning signs and the useful work that should replace it.
There are several distinctions I want to keep clear. AI assistance, sponsorship, affiliate publishing and owning several websites can all have legitimate uses. The question is what has actually been built and why. Likewise, losing credit from artificial links, receiving a manual action and losing a rich-result feature are different outcomes. A falling traffic chart cannot diagnose all three.
How I’m ordering the risks of black hat SEO techniques
Black hat SEO means attempting to manipulate search visibility through practices that breach the relevant search platform’s rules. This guide concentrates on Google web search, with clearly identified Google Business Profile and Maps entries.
The order below is my editorial assessment of potential damage when a practice is used substantially on an otherwise legitimate business website. I weigh the reach of the problem, the visibility at stake and the work needed to undo it. The top entries can affect whole publishing processes or link portfolios; later ones are often more contained. Adjacent positions are judgment calls, not measured penalty probabilities.
A local business dependent on Maps should move fake profiles and review manipulation much higher on its own checklist. Security compromises require immediate attention regardless of where an SEO tactic appears here. None of the lower positions is a recommendation to try it.
| Technique |
Warning sign to investigate |
What may be at stake |
First response |
| 1. Scaled content abuse |
Huge output targets, little original input |
Visibility across large content sets |
Stop the production process; sample its output |
| 2. Manufactured link networks |
One supplier controls the referring sites |
Link credit and a distributed cleanup |
Obtain the complete placement list |
| 3. Cloaking |
Search engines receive different substantive content |
Affected pages or wider site visibility |
Compare crawler and visitor versions |
| 4. Site reputation abuse |
A partner mainly wants the host’s ranking signals |
Treatment of the hosted section |
Review the arrangement and current policy |
| 5. Sneaky redirects |
Some visitors land somewhere unexpected |
Search visibility and visitor trust |
Trace the redirect and its source |
| 6. Expired domain abuse |
Old links are the business plan |
Visibility of the repurposed site |
Examine domain history and new content |
| 7. Policy circumvention |
Spam is moved or restored after enforcement |
Further action and a harder review |
Fix the underlying practice |
| 8. Paid links passing ranking credit |
Payment depends on a “dofollow” link |
Link credit; potential manual action |
Review the deal and link attributes |
| 9. Doorway pages |
Near-identical entry pages funnel to one destination |
Visibility of the doorway campaign |
Check what each page actually provides |
| 10. Guest-post link factories |
Placements are sold by count and anchor text |
Link credit and publisher relationships |
Inspect actual publications and articles |
| 11. Fake Business Profiles |
Invented locations or misleading business details |
Profile visibility and eligibility |
Correct details and check eligibility |
| 12. Fake or manipulated reviews |
Incentives, invented customers or selective solicitation |
Reviews and profile restrictions |
Stop the scheme; retain records |
| 13. Scraping and article spinning |
Competitors‘ work repackaged without new value |
Visibility and editorial credibility |
Trace sources and commission original work |
| 14. Thin affiliate publishing |
Merchant copy with a purchase button |
Visibility of low-value pages |
Add useful comparison or remove the page |
| 15. Excessive link exchanges |
A quota of reciprocal or circular placements |
Link value and cleanup obligations |
Separate genuine references from trades |
| 16. Automated comment and directory spam |
Thousands of submissions sold as a package |
Wasted budget and spam-link exposure |
Stop submissions; inspect delivered URLs |
| 17. Manipulative widget and template links |
Distributed embeds carry compulsory SEO anchors |
Unnatural outbound and inbound links |
Review the distributed code and links |
| 18. Fake tools and misleading functionality |
Promised functionality never materialises |
Visitor trust and search eligibility |
Test the actual user journey |
| 19. Hidden text and links |
Ranking text concealed from ordinary visitors |
Affected-page visibility |
Check templates and hidden elements |
| 20. Keyword stuffing |
Repetition displaces useful information |
Page quality and search visibility |
Rewrite around the reader’s task |
| 21. Deceptive structured data |
Markup invents facts absent from the page |
Rich-result eligibility |
Compare markup with visible evidence |
| 22. Click bots and fabricated engagement |
Bought searches or scripted visits sold as SEO |
Budget, measurement quality and policy exposure |
Demand evidence; reject manufactured activity |
1. Scaled content abuse
I put this first because a bad production system keeps manufacturing the problem. One poor article is an editing job. A process generating thousands of pages without meaningful original input is a much larger operational commitment.
Google’s guidance on generative AI content warns against producing large quantities of pages without adding value. Its AI-content guidance also makes clear that appropriate AI use is allowed. A human byline or a person clicking “publish” does not, by itself, establish that the result is useful.
An illustrative warning sign: a supplier proposes a page for every combination of service, town and customer type, but has no plan to collect local information, test anything, interview anyone or verify the claims. The production target is precise. The editorial purpose is remarkably elusive.
I would ask to see ten proposed pages before approving the system. What is different on each? Which statements come from the business? Who checks them? Could the reader make a better decision after visiting one?
If the process is already running, pause new output and audit representative batches. Decide which pages merit substantial improvement, consolidation or removal. Keep a record of the decisions. Deleting everything because a traffic chart fell is no substitute for finding the problem.
2. Private blog networks and manufactured link networks
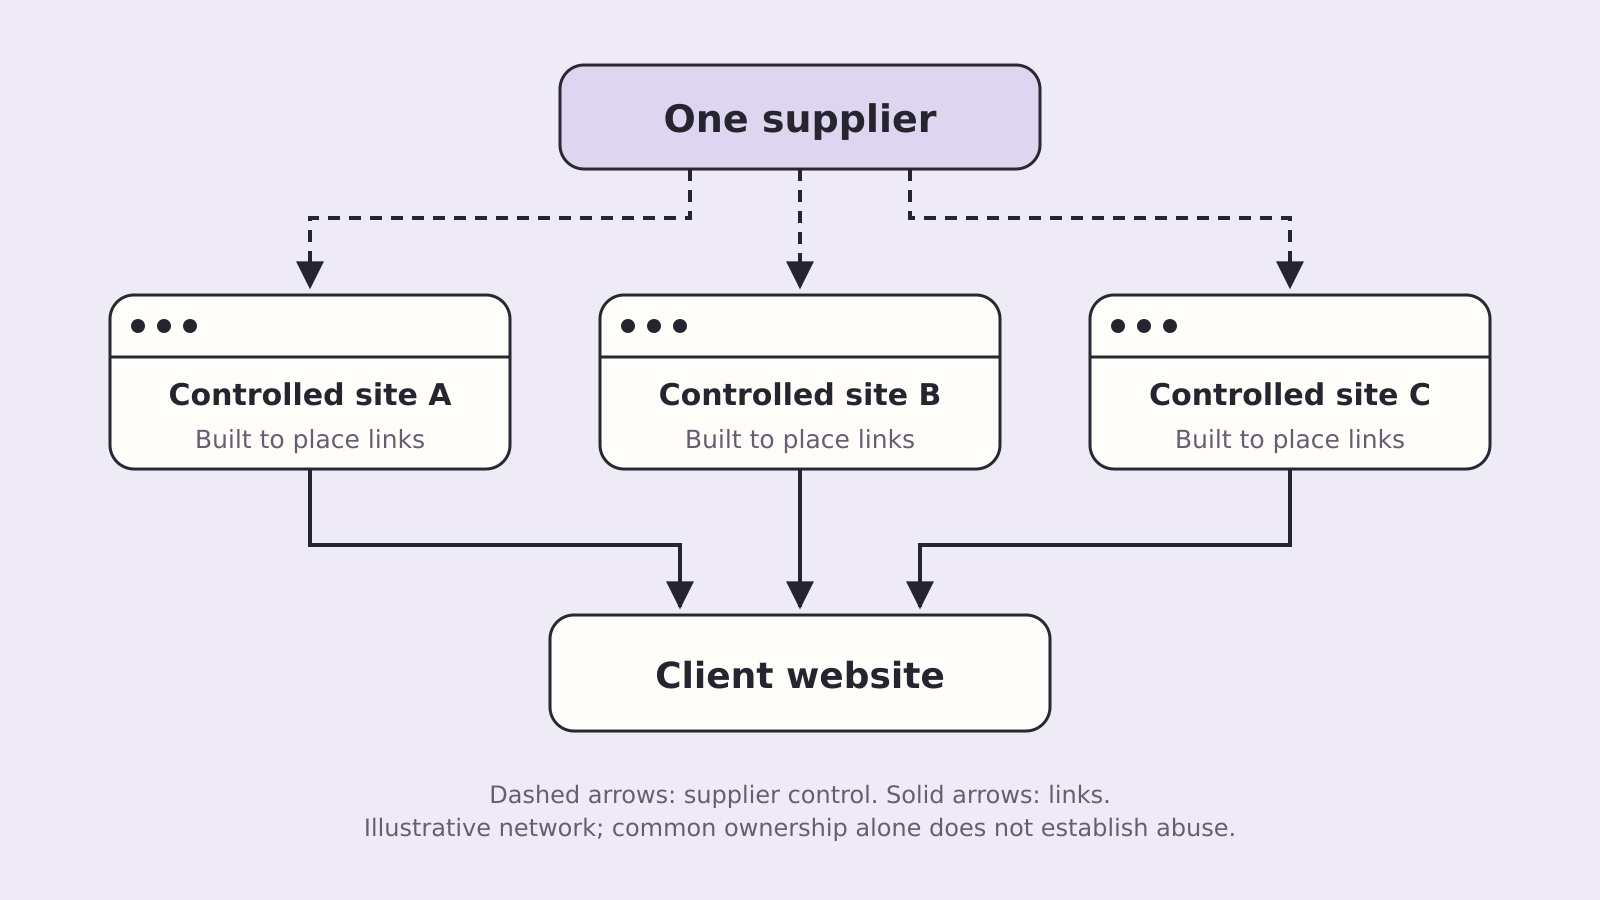
A private blog network, or PBN, is a collection of controlled sites used to manufacture ranking links. Networks can also be assembled through paid placements or intermediary suppliers. Owning several real publications is a different proposition from operating sites chiefly to point links at a customer.
SEW’s 2014 explanation by Eric Enge made that distinction long before the current AI debate. The relevant question remains whether those sites have a purpose and audience of their own.
My concern as a buyer is control. If one supplier created the referring sites, wrote the articles and chose every destination, the apparent diversity of domains may conceal a single dependency. Replacing that arrangement can mean tracing placements across sites you cannot edit.
Ask for the complete list of live URLs, the relationship between the supplier and each publisher, and what happens to the links if the contract ends. Inspect a sample beyond its domain score. Can you identify a real publication, a relevant audience and an article worth reading?
Google says its link-spam systems can neutralise unnatural links, removing the credit they supplied. A ranking decline after that does not automatically mean a human reviewer imposed a manual action.
3. Cloaking
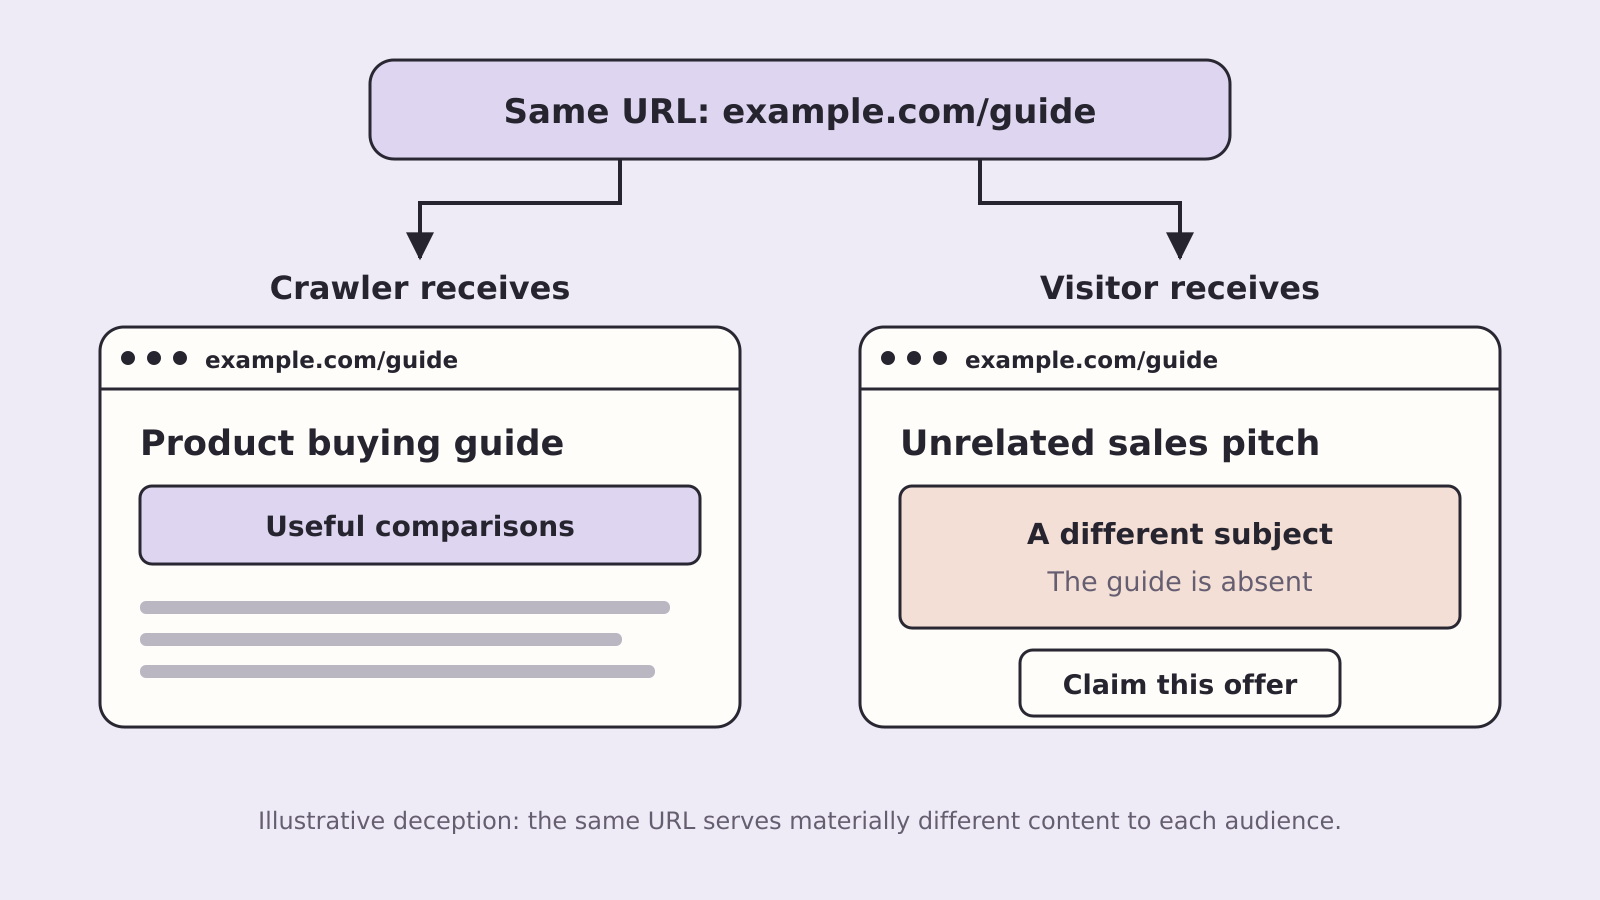
Cloaking deliberately gives a search engine materially different content from the content shown to people, to mislead search or its users. Google’s manual-action documentation describes comparing the version fetched through URL Inspection with the visitor-facing page when investigating this issue.
An illustrative case would be a page presented to a crawler as a substantive product guide while visitors receive an unrelated sales pitch. A claim that customers “do not need to see the SEO version” deserves an immediate explanation.
Ask a developer to check the affected templates, plugins and serving rules. Preserve examples before changing them, then work out whether the difference was deliberate, a configuration problem or an unauthorised modification. A single screenshot cannot tell you which.
There are legitimate reasons for access differences. Google provides specific markup for subscription and paywalled content to distinguish it from deceptive cloaking. A paywall should be assessed against those requirements, not against a simplistic rule that every visitor must see identical pixels.
4. Site reputation abuse
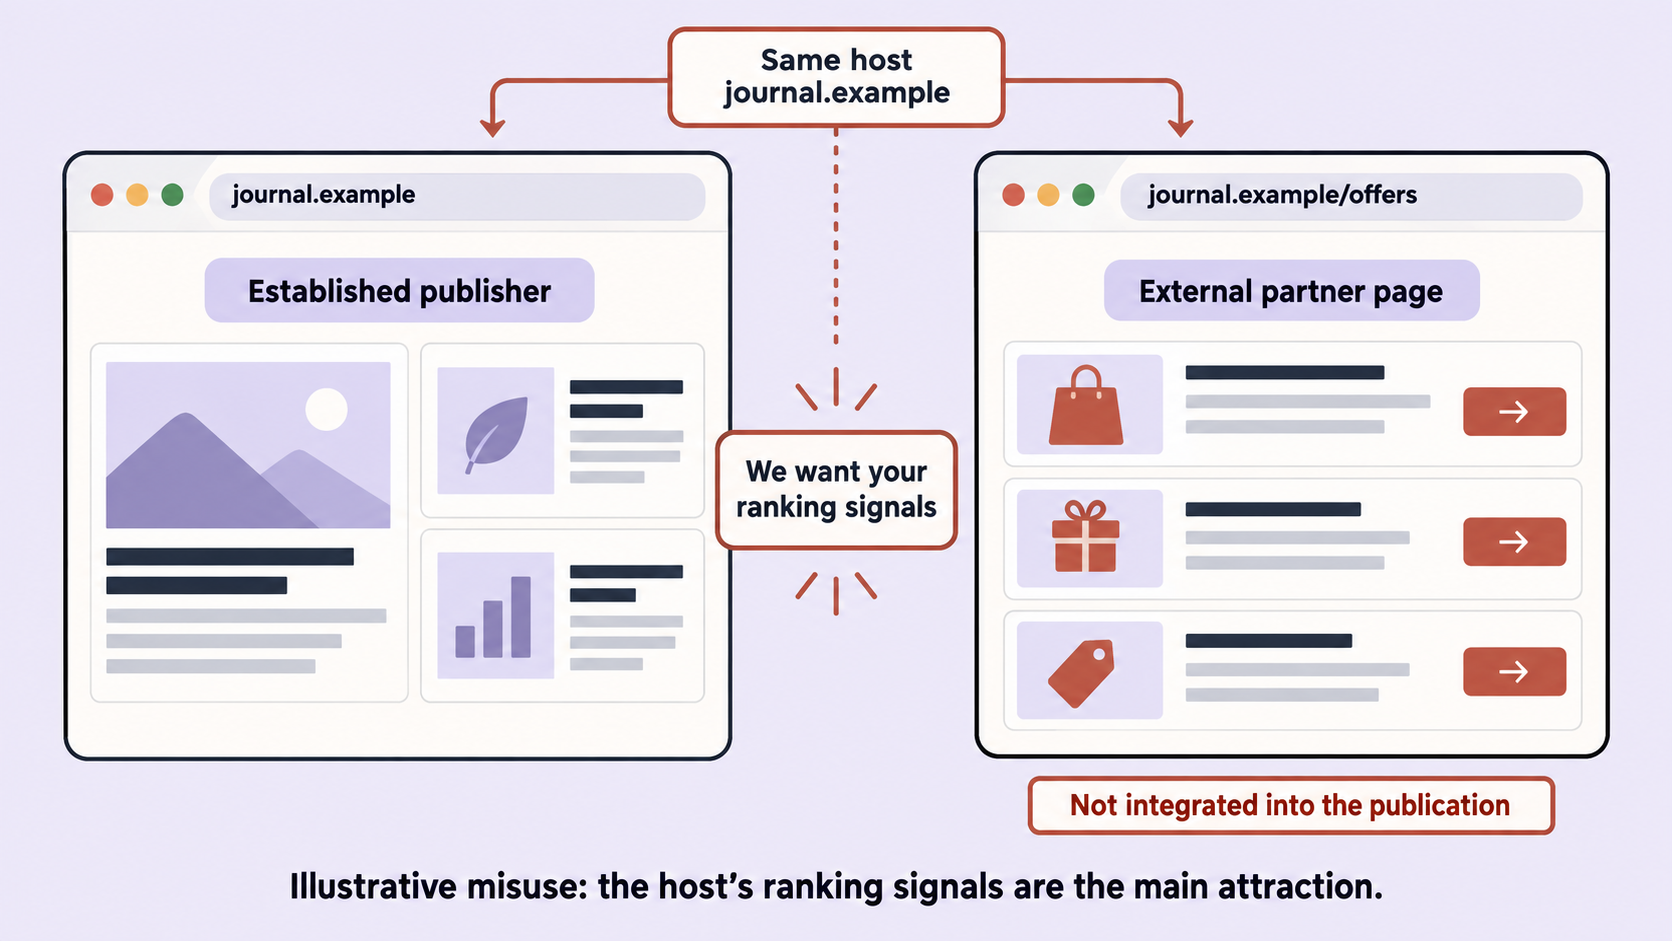
For a publisher, this deserves particular scrutiny. A commercial proposal can look attractive precisely because someone else supplies the content and administration. I would want to know why the partner needs our domain, who the section serves and what responsibility we retain for it.
Google’s current site reputation policy concerns third-party content hosted mainly to benefit from the host’s established ranking signals. Third-party authorship alone does not establish a violation.
The policy now distinguishes geography: affected pages may face manual action in results outside the EEA; within the EEA, Google describes potentially treating the section separately from the main domain, without that manual-action impact. Its current guidance also discusses the host’s editorial contribution and integration. Those details matter when evaluating a real arrangement.
For my own review, I would ask: would we commission this section for our readers? Who verifies it? Is it integrated into our editorial work? Can we remove or change it without a partner’s permission? Is the sales pitch principally about the audience, or the ability to rank on an established domain?
Treat those as due-diligence questions, not a mechanical test that guarantees compliance. A logo, a byline and a disclaimer cannot answer the commercial-purpose question on their own.
5. Sneaky redirects
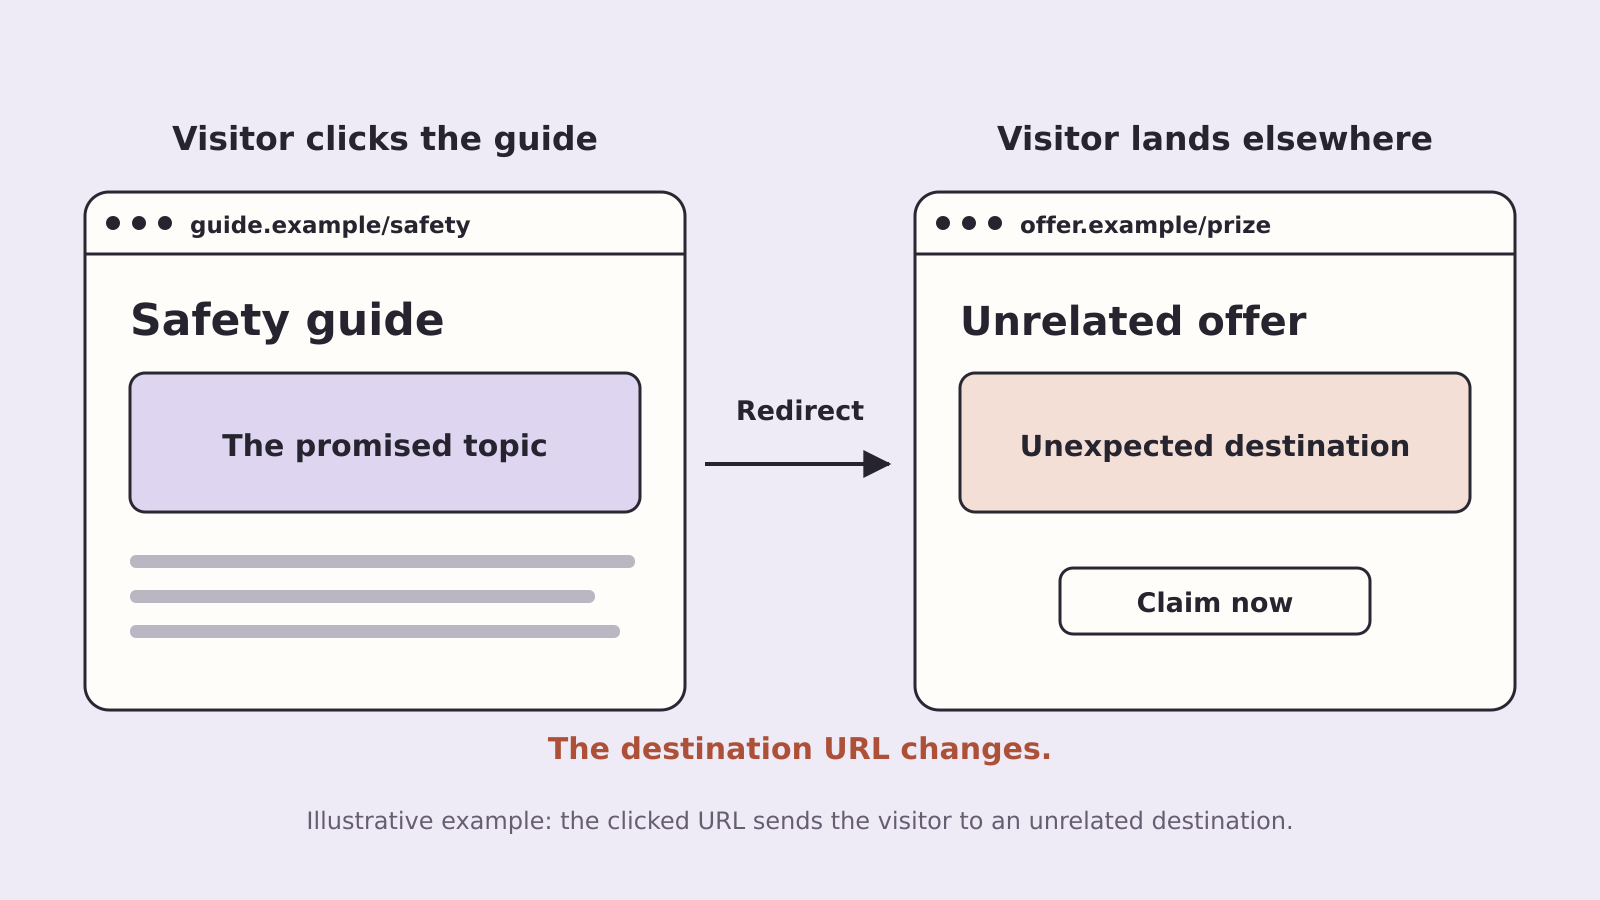
A redirect becomes deceptive when it sends visitors to an unexpected destination while concealing that behaviour from search engines or other visitors. A normal site migration or a sensible replacement for an old page has an entirely different purpose.
This is also an ownership problem. Google has documented mobile redirects introduced through advertising code and hacked sites, sometimes without the owner’s knowledge.
If a customer reports an unrelated destination, reproduce the journey they describe: the original link, device type and page. Ask a developer to inspect the redirect chain and the code responsible. Test safely; an unfamiliar destination could be harmful.
An agency proposal to send search visitors somewhere different from the page being ranked should explain the user benefit in plain language. “Preserving the SEO page” is not an adequate explanation for deceiving people who click it.
Check navigation too. Google identifies back-button hijacking, which prevents people from returning normally to the previous page, as a malicious practice. A script that traps a visitor deserves removal, not a favourable engagement report.
6. Expired domain abuse
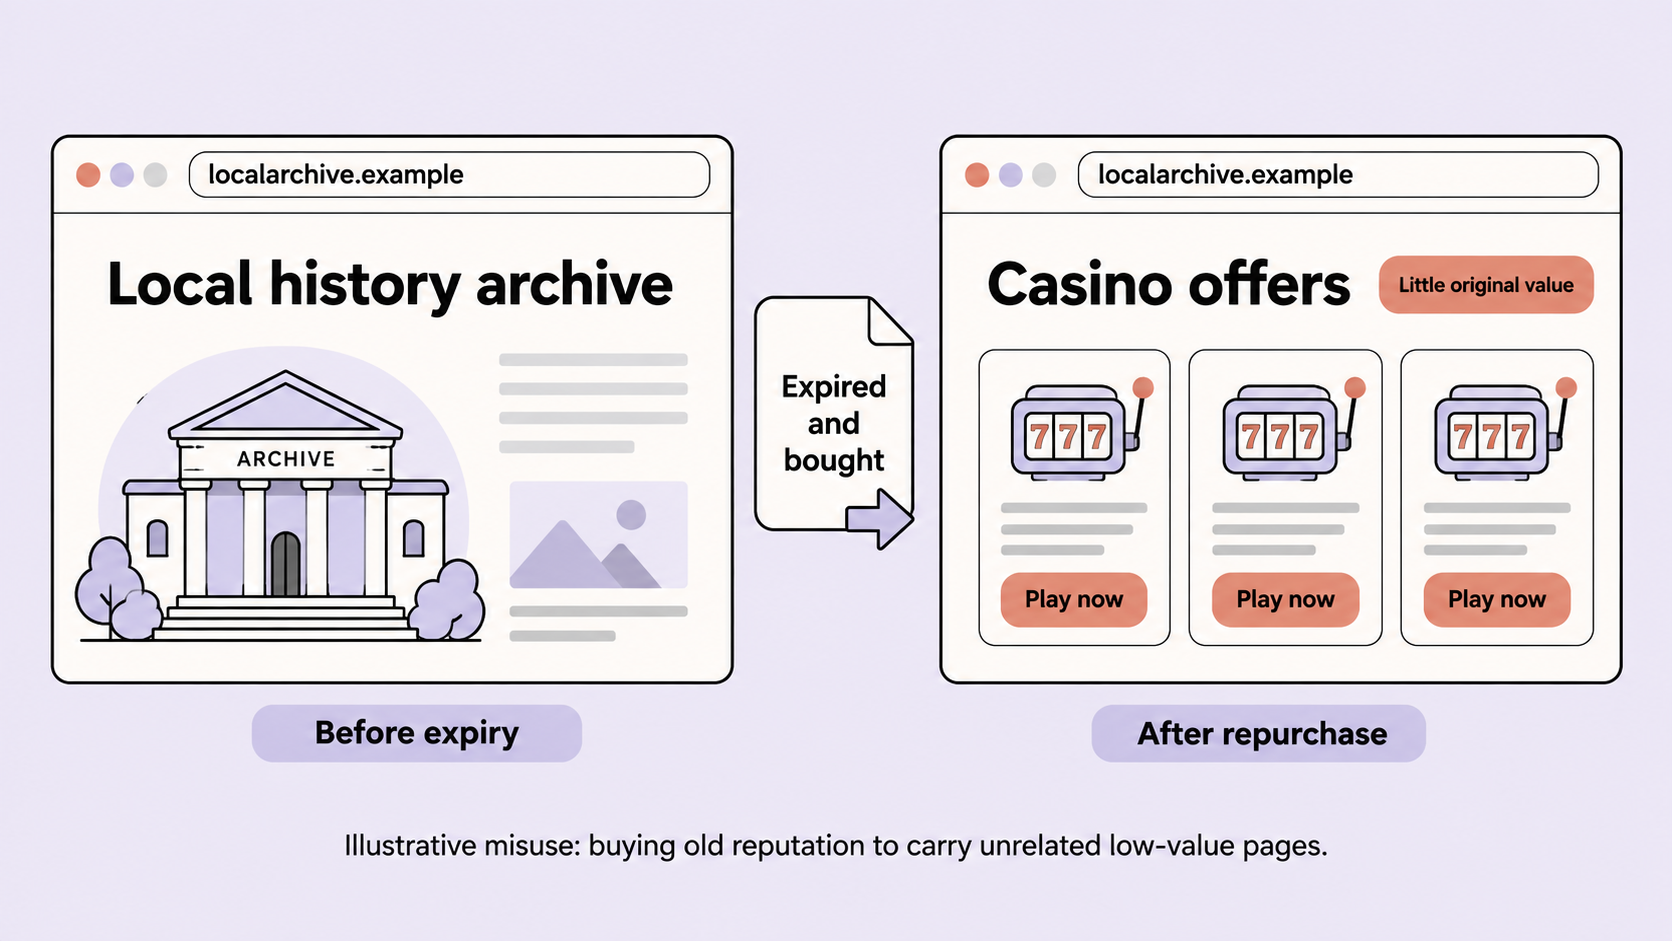
An old domain can be a legitimate business asset. The abusive version buys its previous reputation, installs low-value material and expects the historical signals to do the work.
When Google introduced its expired-domain policy in March 2024, it distinguished that practice from creating a useful new site on an old domain. Age alone does not decide the issue.
As a publisher, I would separate the value of the brand, archive, audience and business from a sales pitch built entirely around backlinks. An illustrative warning sign is a seller who can discuss every historical authority metric but cannot explain the intended readership of the replacement website.
Inspect the domain’s history, the relevance of its existing references and the substance of the proposed operation. Redirecting an acquired domain into another site also deserves a proper migration rationale. An acquisition is not a universal exemption from scrutiny, and an expired registration is not proof of abuse.
7. Moving or restoring spam to evade enforcement
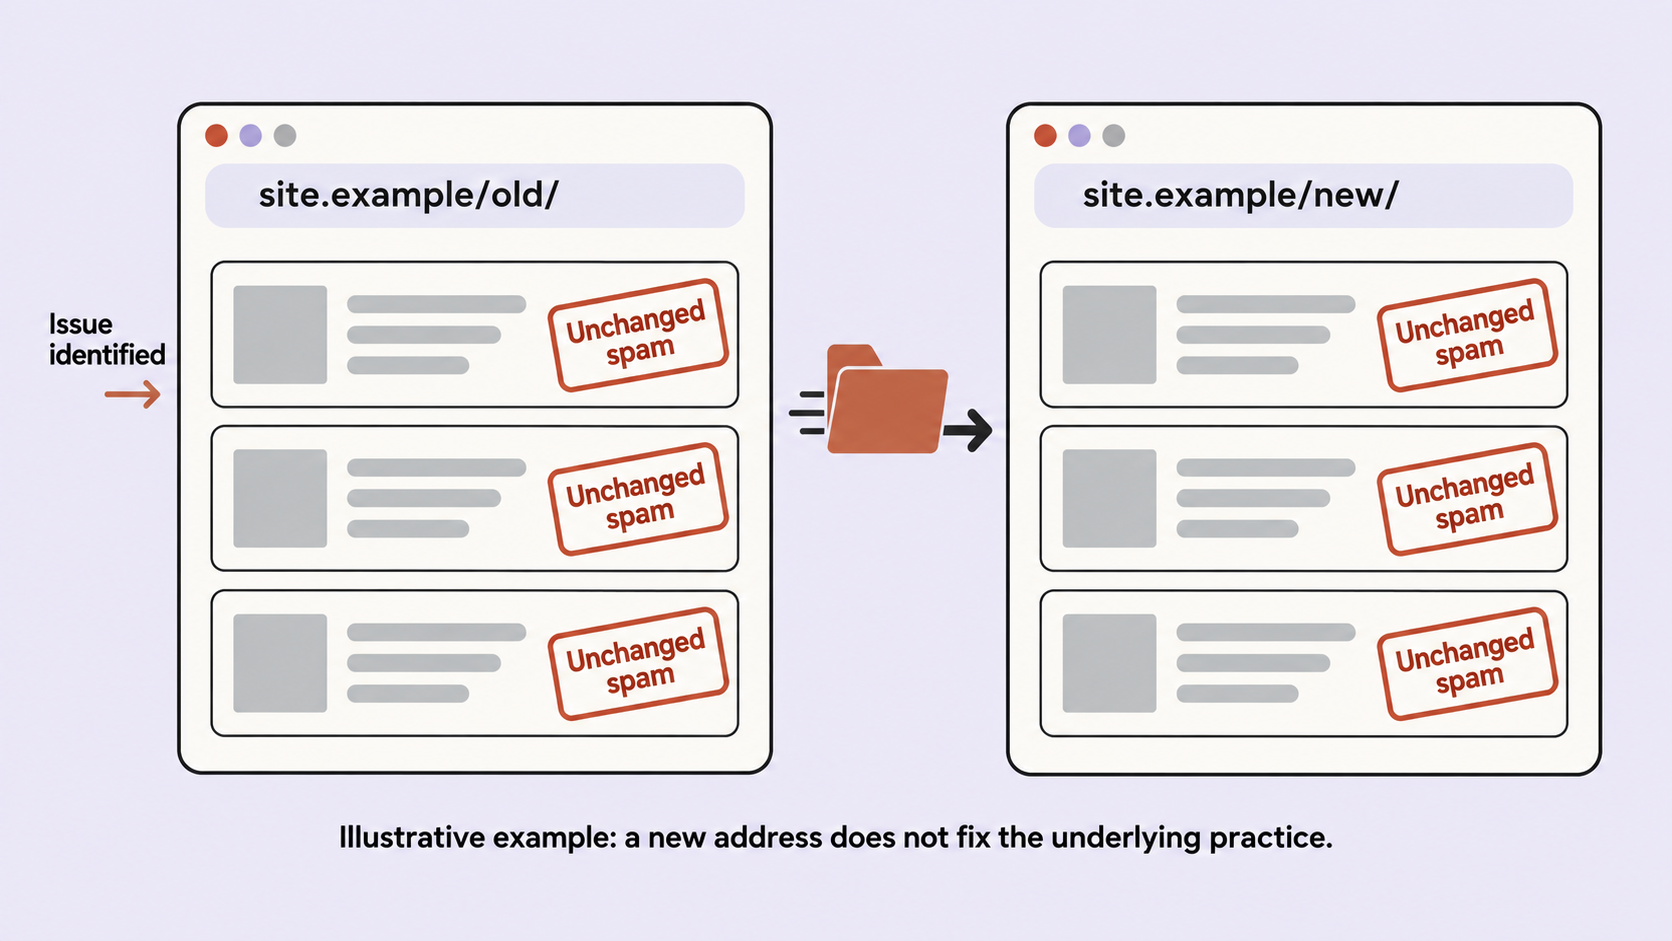
Once a problematic practice has been identified, moving it to a new address while continuing the same operation creates another risk. So does temporarily fixing a violation to obtain reconsideration, then restoring it.
Google’s warning about repeated violations gives the example of qualifying an unnatural link for review and subsequently removing that qualification. It says repeated deliberate violations can bring further action and make reconsideration harder.
I would be particularly wary of an adviser whose recovery plan consists mainly of replacing a domain, folder or account. Ask what changes in the underlying content, links or business process. A different URL is easy to put on an invoice. It is less useful when the operation behind it is unchanged.
This entry concerns deliberate evasion. A legitimate migration or a good-faith restructuring needs to be assessed on its own facts.
8. Buying or selling links that pass ranking credit
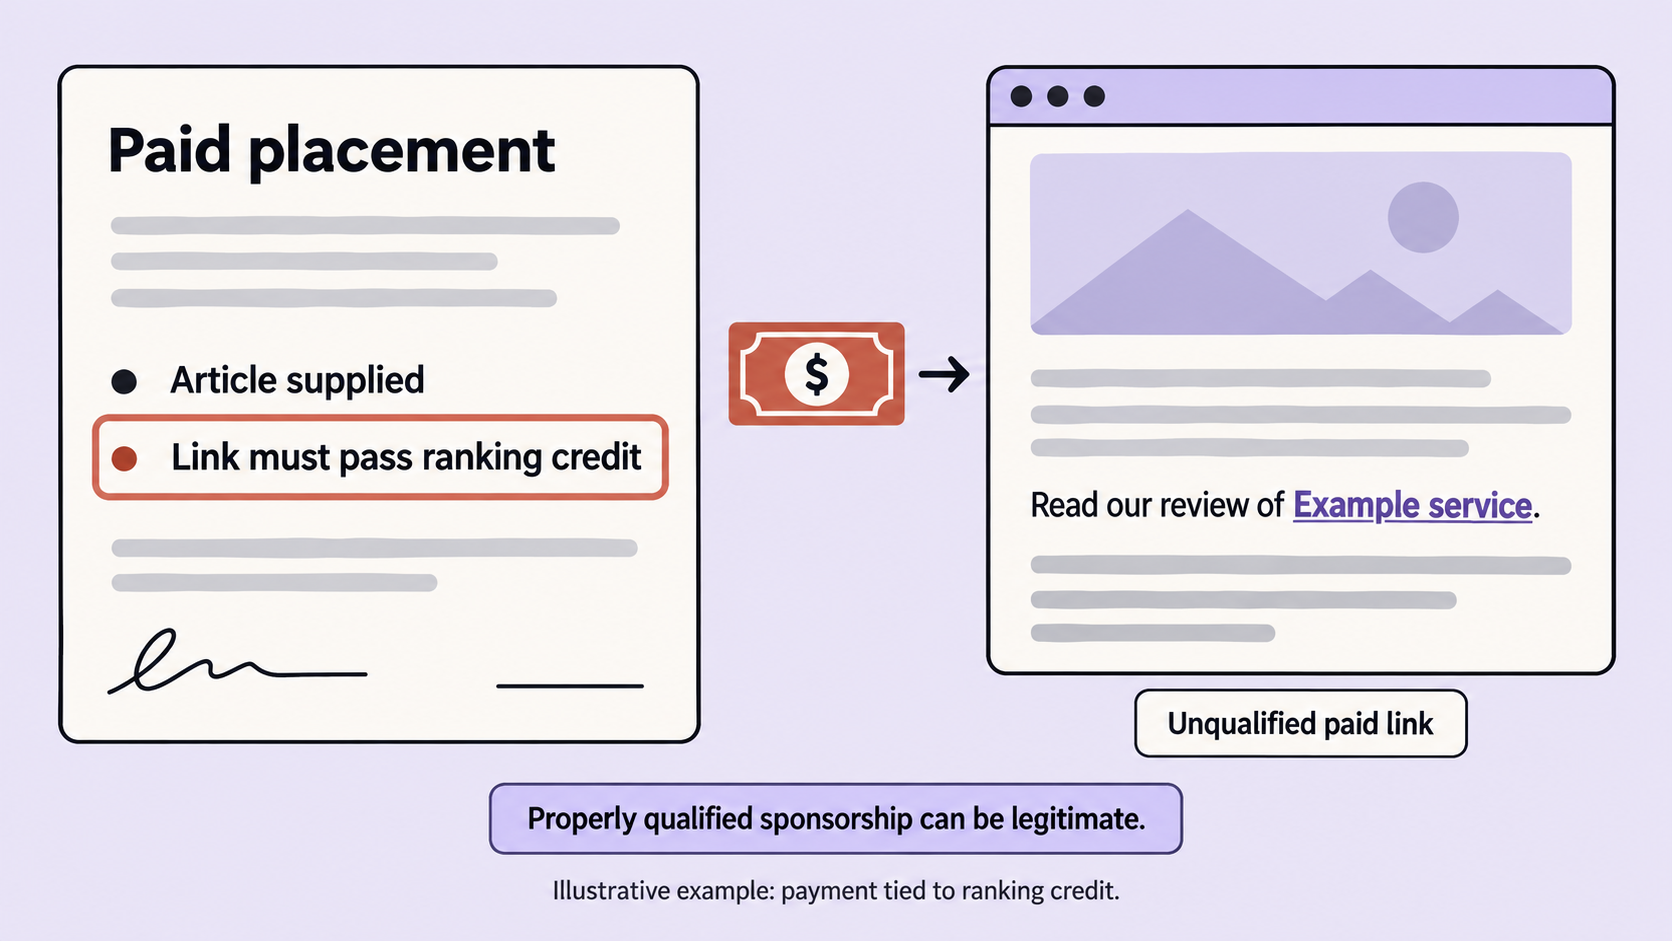
Paid advertising and sponsorship are normal publishing activities. Google’s outbound-link guidance specifies rel="sponsored" for paid placements; nofollow remains acceptable for that purpose. The warning sign is a deal that depends on passing ranking credit.
An illustrative sales condition: the placement is only available if the publisher promises a permanent, unqualified link with a particular commercial anchor. That is worth examining before anybody pays.
Review what the purchase actually buys: exposure to an audience, qualified traffic, a useful sponsored resource, or a ranking signal. A sponsorship label informs the reader; link attributes serve a separate technical purpose. Check both.
For existing placements, obtain the URLs and contractual terms. Where the arrangement violates policy, seek correction or removal. Do not immediately upload a blanket disavow file: the conditions for using that tool are narrower than “a backlink tool coloured this domain red.”
9. Doorway pages and interchangeable location pages
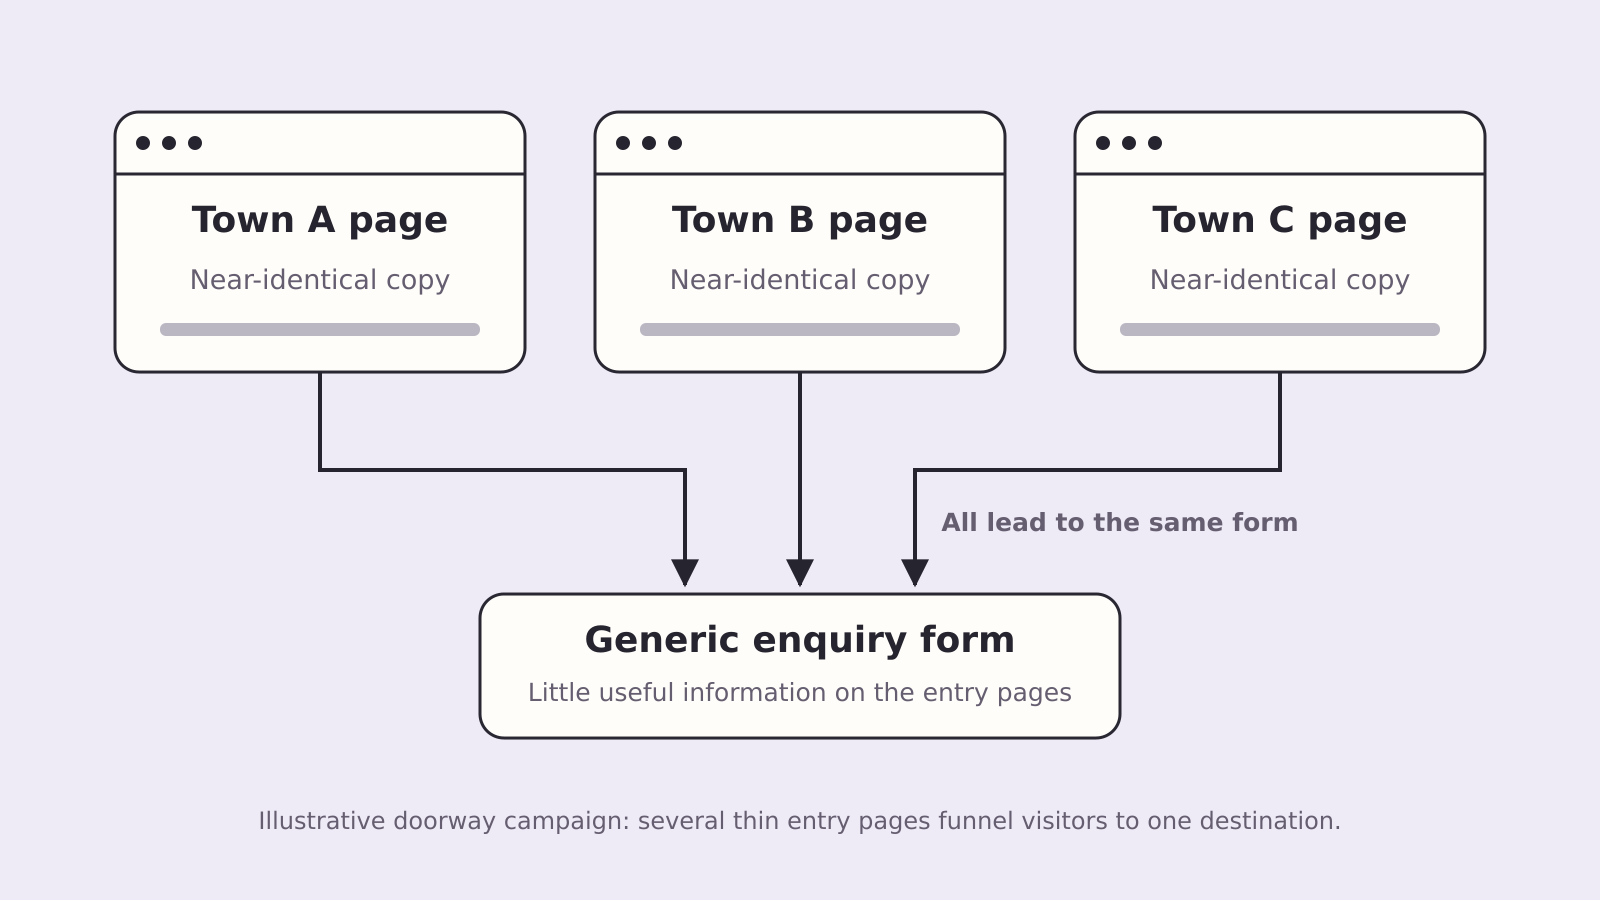
Doorway pages capture variations of a query and funnel people toward substantially the same destination, without doing enough useful work themselves. They can sit on one domain or many. Google’s doorway-page explanation focuses on their function in the user journey.
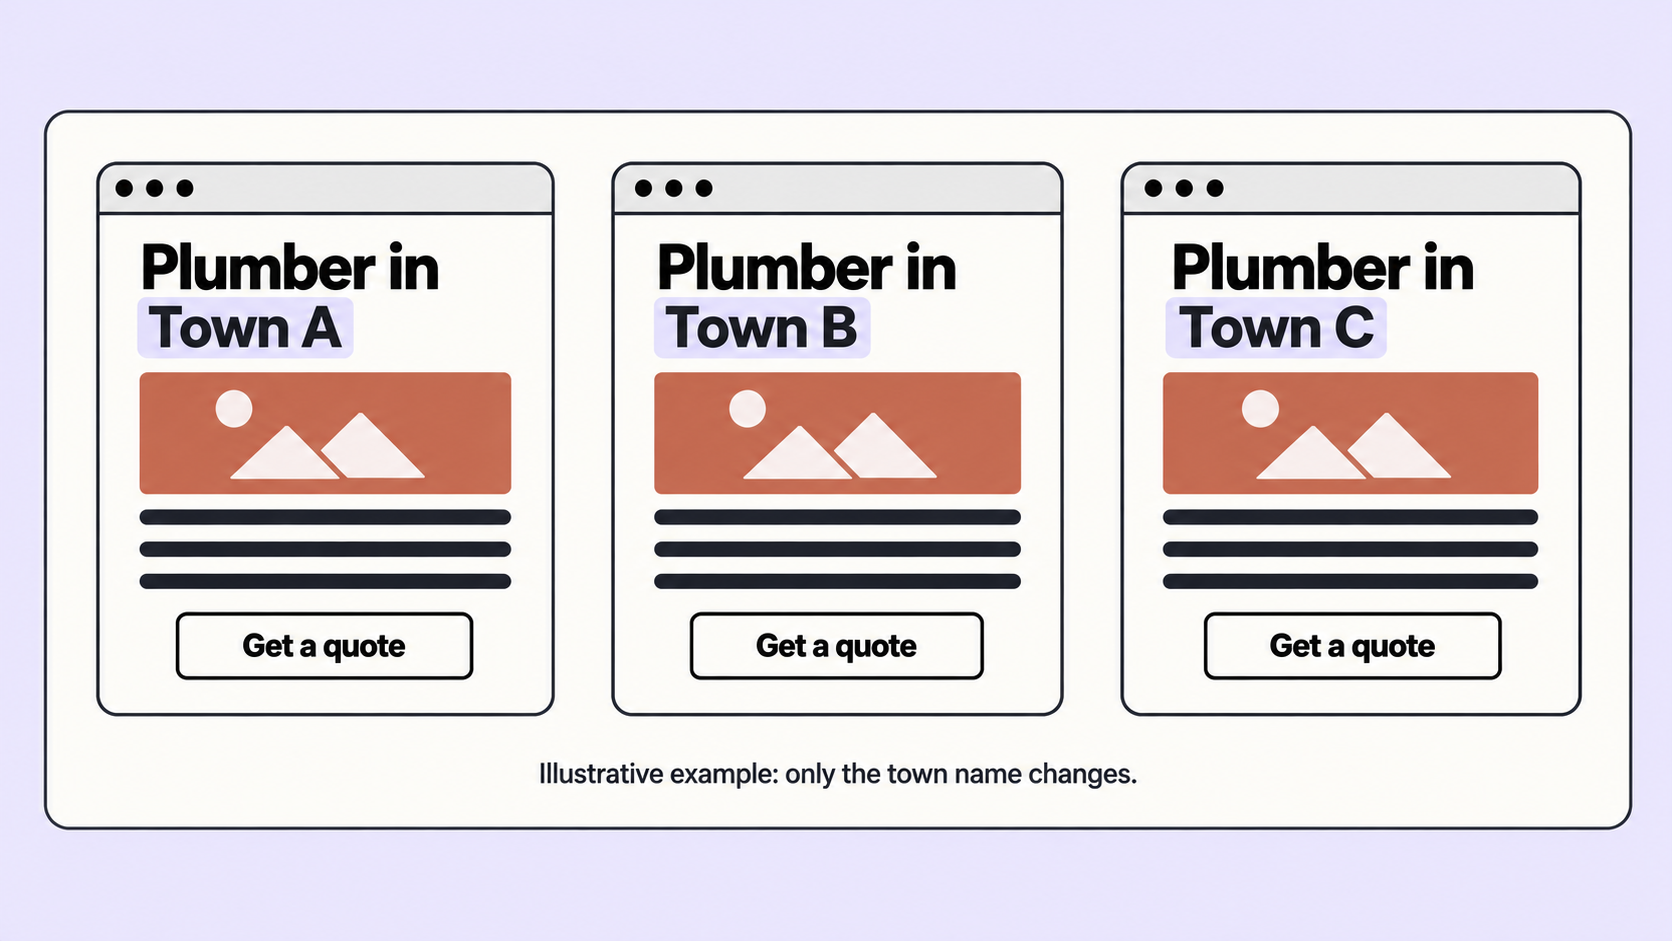
Consider a hypothetical service business with a separate page for every town around it. If each page offers accurate service availability, relevant examples and useful local details, there may be a reason for it to exist. If only the town name changes before the visitor is sent to a generic enquiry form, I would question the entire set.
Ask what a person in that location learns from the page. Audit several neighbouring pages together, rather than approving one attractive template in isolation. Consolidate where the information belongs together; retain separate pages where the business can genuinely support the distinction.
Doorways and cloaking can overlap, but they describe different problems. A page can be a doorway without hiding its content from anyone.
10. Guest-post factories and distributed anchor-text campaigns
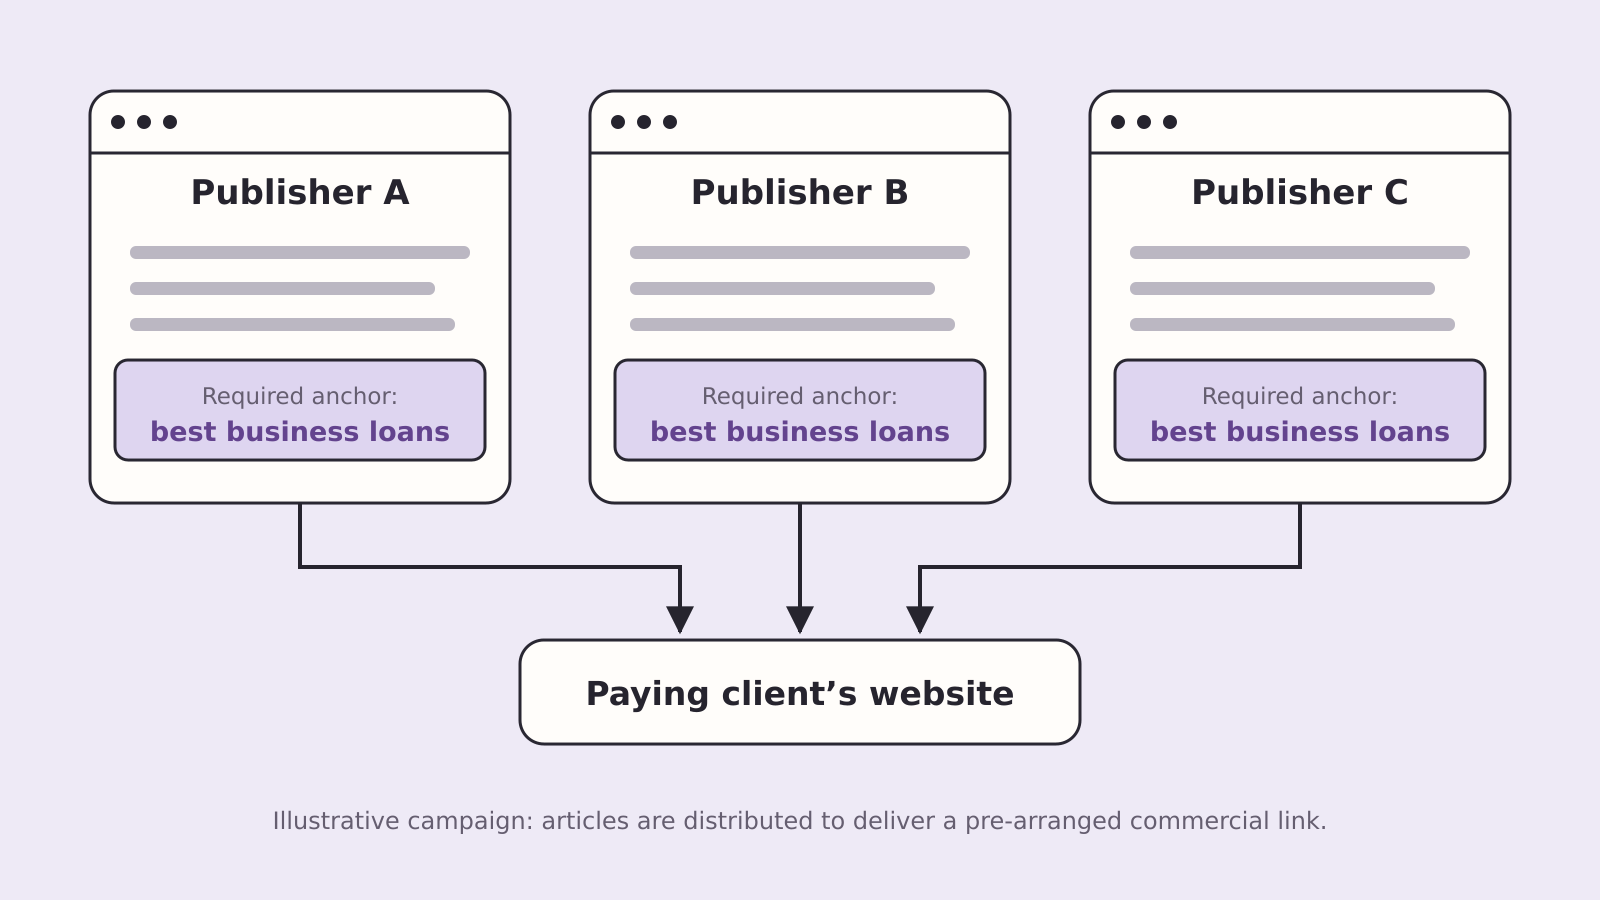
Guest contributions can bring valuable expertise to a publication. The troublesome version treats the article as packaging for a pre-arranged link, repeated across numerous sites.
Google’s guidance on large-scale article campaigns identifies patterns such as keyword-heavy links, repeated content and writers with little subject knowledge when the main purpose is manufacturing links. Its commercial-link guidance also covers sponsored and guest-post arrangements.
Ask to inspect the articles, not just the publisher logos in the proposal. Is there an argument, evidence or experience a reader would value? Does the destination help explain that article? Who decided the link belonged there?
I would commission the expertise first and assess the reference in context. A genuinely useful contribution can survive an editor changing an anchor or removing an unnecessary link. If the entire transaction falls apart at that point, the article’s supposed purpose deserves a second look.
11. Fake Business Profiles, locations and business details
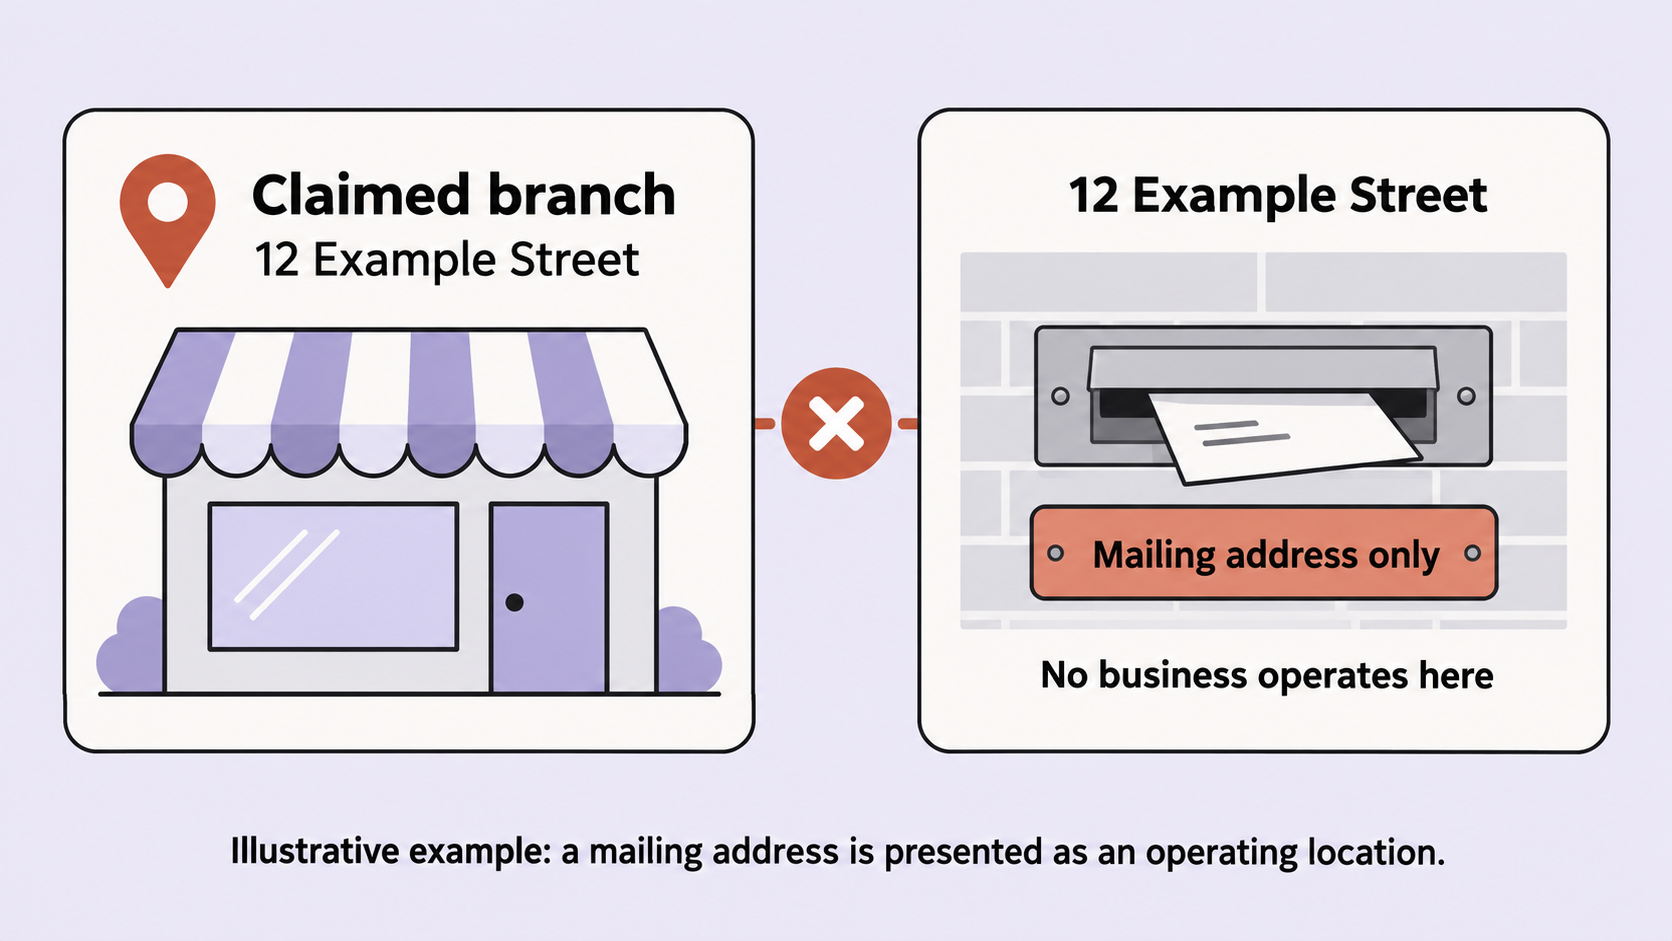
This is a Google Business Profile and Maps issue. For a local operator, losing the profile through which customers find the business can be more serious than many website problems higher on this list.
Google’s business-representation guidelines require accurate information. They exclude a rented mailing address where the business does not operate; co-working locations must meet stated requirements. Names should reflect the business’s real-world identity, rather than an invented string of services and towns.
A hypothetical agency offering to create branches in places where you have no qualifying operation should explain how each location is eligible. Ask who owns each profile and which address, signage, staffing and customer-facing activity supports it.
Use accurate service areas and legitimate locations. If the existing profile has incorrect information, correct the facts and follow the relevant support process. Creating a replacement identity to escape a restriction risks compounding the problem.
12. Fake reviews, incentives and review gating
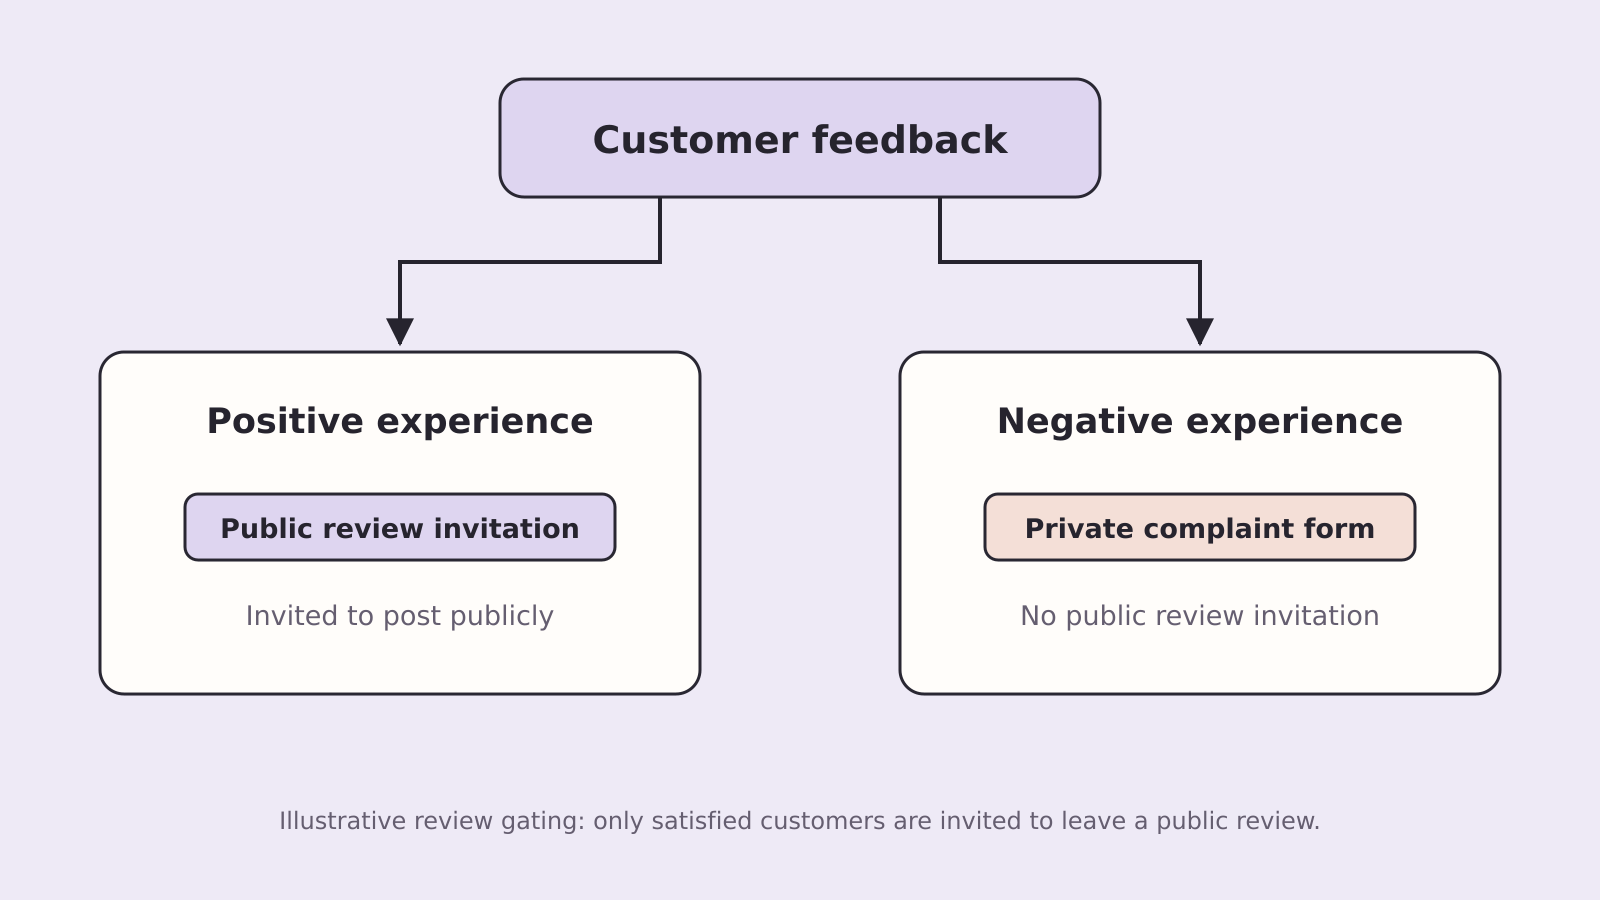
Buying reviews, inventing customers, rewarding review submissions and manipulating who gets invited to post can turn reputation management into evidence of a scheme. Google Maps‘ contribution policies prohibit fake engagement and rating manipulation, including incentives and selective solicitation of positive reviews.
The possible consequence extends beyond removing a few stars. Google lists Business Profile restrictions that can include temporarily preventing new reviews, unpublishing existing reviews or displaying a warning about removed fake reviews.
I would examine the actual request customers receive. A neutral invitation sent through a consistent process is very different from a funnel that routes satisfied customers to Google while diverting everyone else into a private complaint form.
Stop incentives and fabricated submissions. Keep the correspondence and vendor records so the business can explain what happened. Build a review-request process around genuine experience, and answer legitimate criticism without making its removal the condition for a refund or benefit.
13. Scraping and article spinning without added value
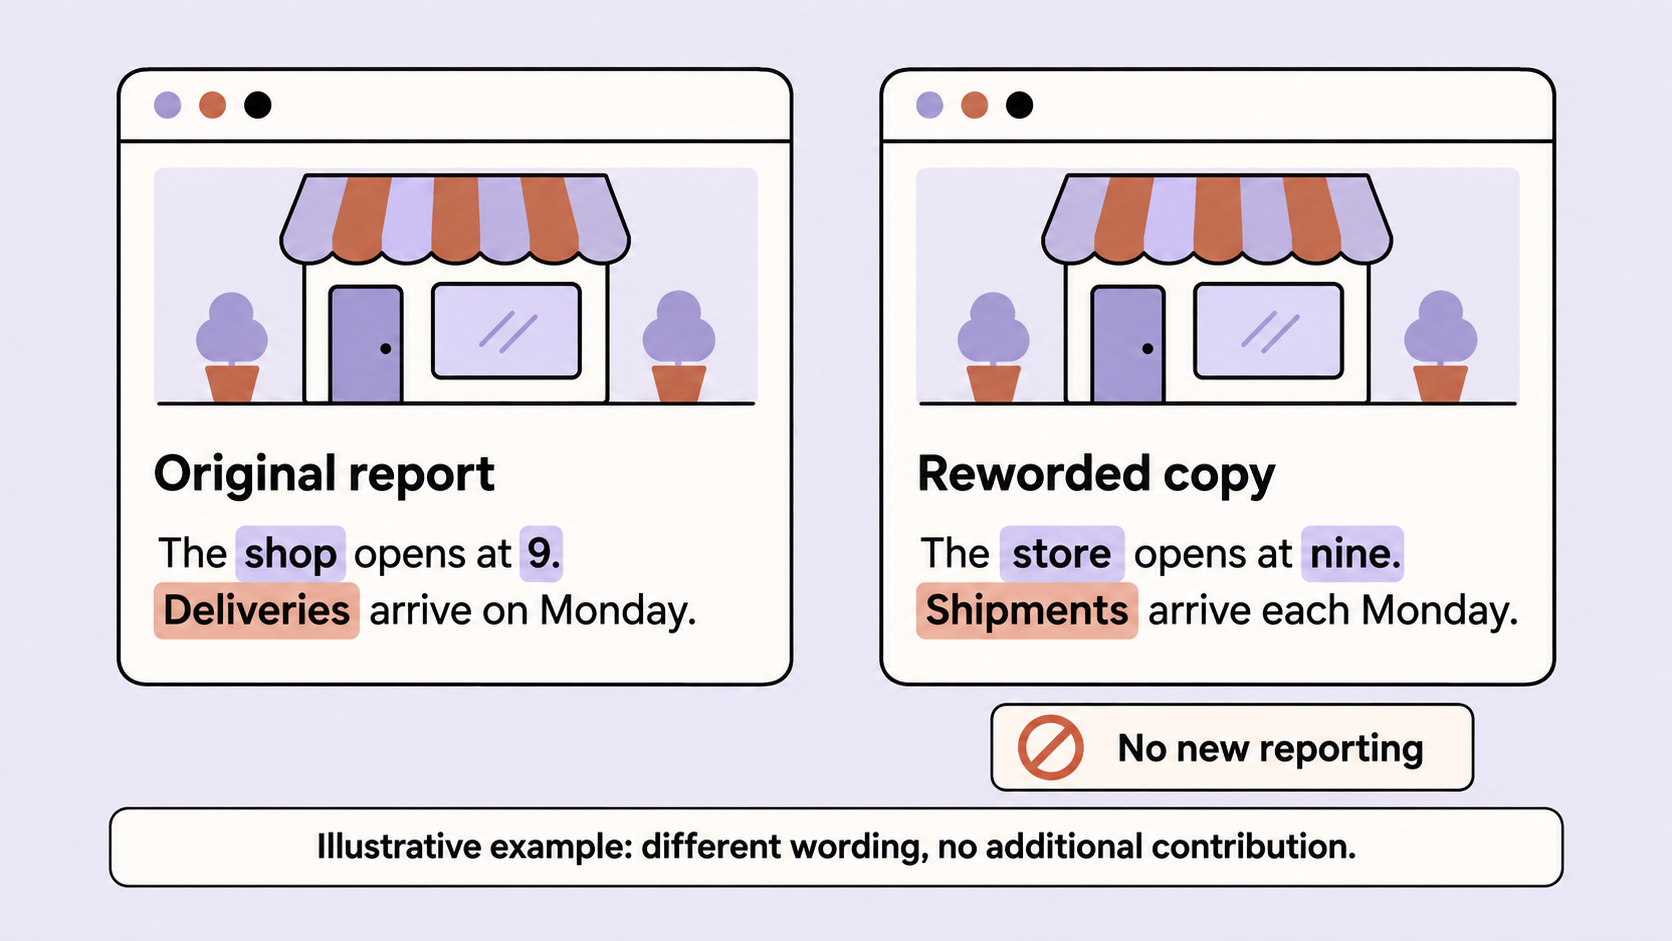
Changing the wording of someone else’s article does not create a new investigation. Nor does translating it, combining several sources or replacing their examples with synonyms establish an original contribution.
Google has long warned about republishing or syndicating material without a substantial added benefit. At scale, this also belongs in the production problem described at the top of this list.
For a publisher, the useful question is editorial: what have we contributed that the sources did not? That could be a verified test, a new interview, a calculation, a correction, an explanatory example or a comparison that changes a decision. A rewrite that preserves somebody else’s reporting and adds a longer introduction does not answer it.
Trace the claims and credit the reporting you use. Commission the missing work before publication. If syndication is authorised, handle it as syndication, with appropriate attribution and indexing decisions, rather than presenting another publication’s work as your own.
14. Thin affiliate pages dressed up as recommendations
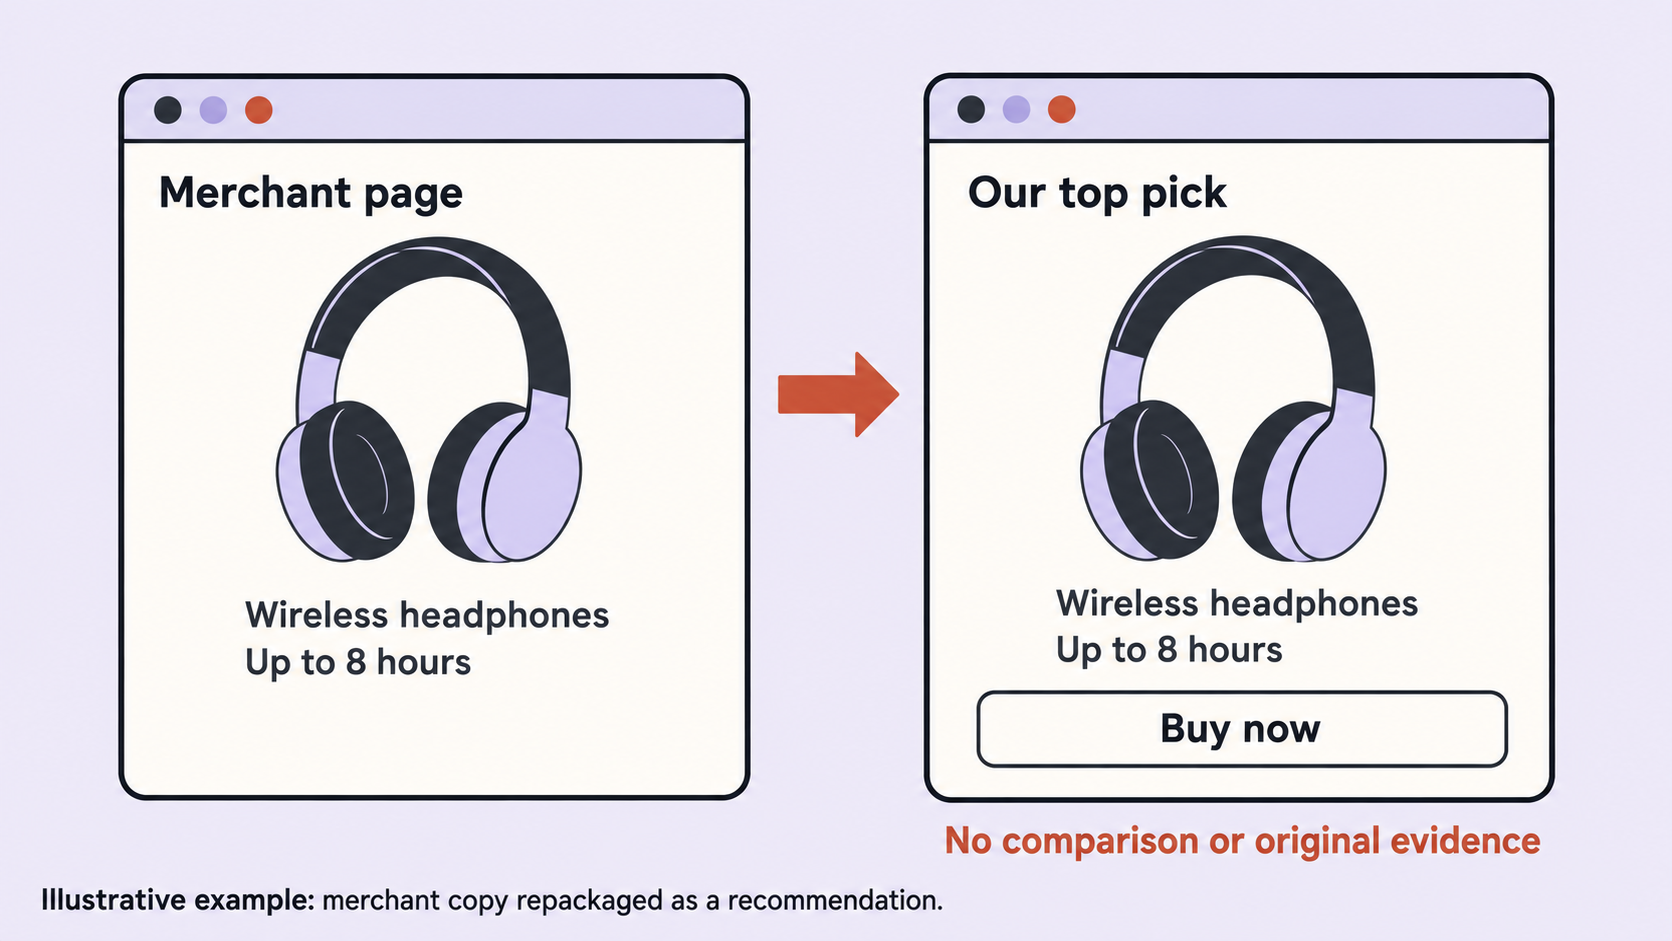
An affiliate page earns its place by helping someone decide. A copied product description with an affiliate button adds little to what the merchant already provides.
Google’s review-writing guidance asks for evidence and useful comparisons, including measurements or first-hand support where the review claims them. That is a sensible editorial standard for a buyer’s guide too.
My test would be to remove the purchase buttons temporarily. Does the page still help the reader choose? A useful comparison might explain a restrictive contract, a missing integration, a test result or a cost that appears only after a particular threshold. The claims need evidence; the page does not need a fictional testing laboratory.
Keep affiliate links appropriately qualified, explain material commercial relationships and let the recommendation follow the findings. If the article cannot explain its choices without repeating vendor descriptions, it needs more reporting.
15. Excessive reciprocal and circular link exchanges
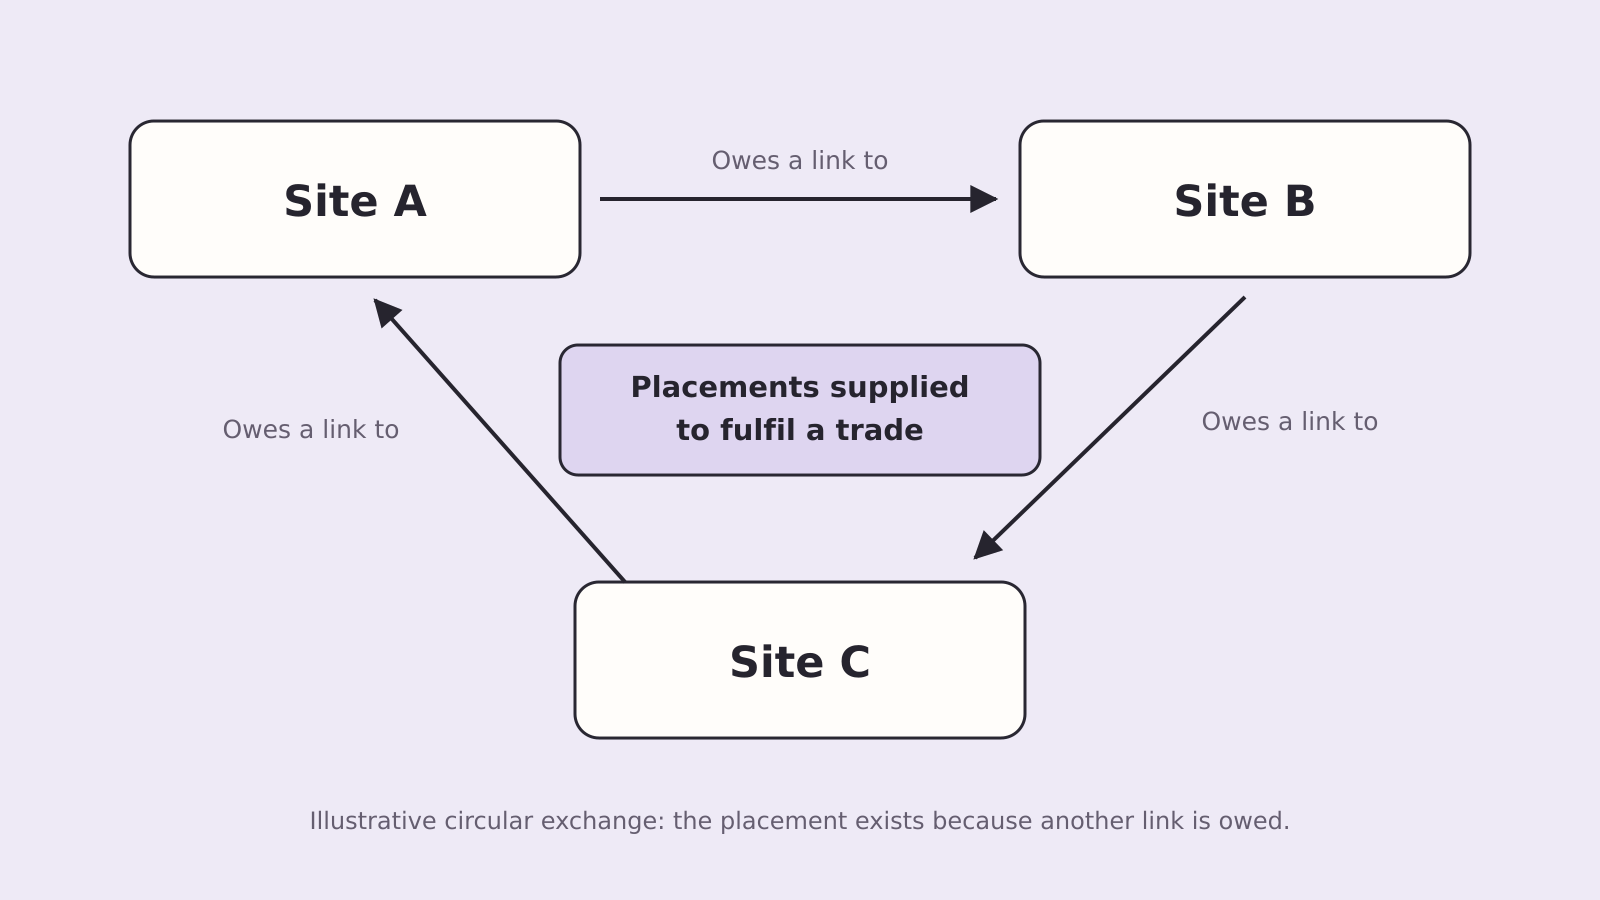
Two organisations can legitimately reference one another. An organised trading programme is a different consideration: the link is owed because another link was supplied.
Google’s guidance on obtaining quality links warns against random exchanges and low-value mass submissions. Adding a third participant to a trade does not provide an editorial reason for the reference.
A useful audit question is whether the destination would remain in the article if the reciprocal obligation disappeared. Ask the supplier for its exchange records and check the context of each placement. Separate real professional references from links inserted to settle a quota.
I would put the effort into something a relevant publisher has a reason to cite. SEW’s first-hand account of content-led link campaigns explains why the reference has to make sense in the story. Paying for useful research or outreach work is distinguishable from arranging a link trade.
16. Automated comment, forum, profile and directory spam
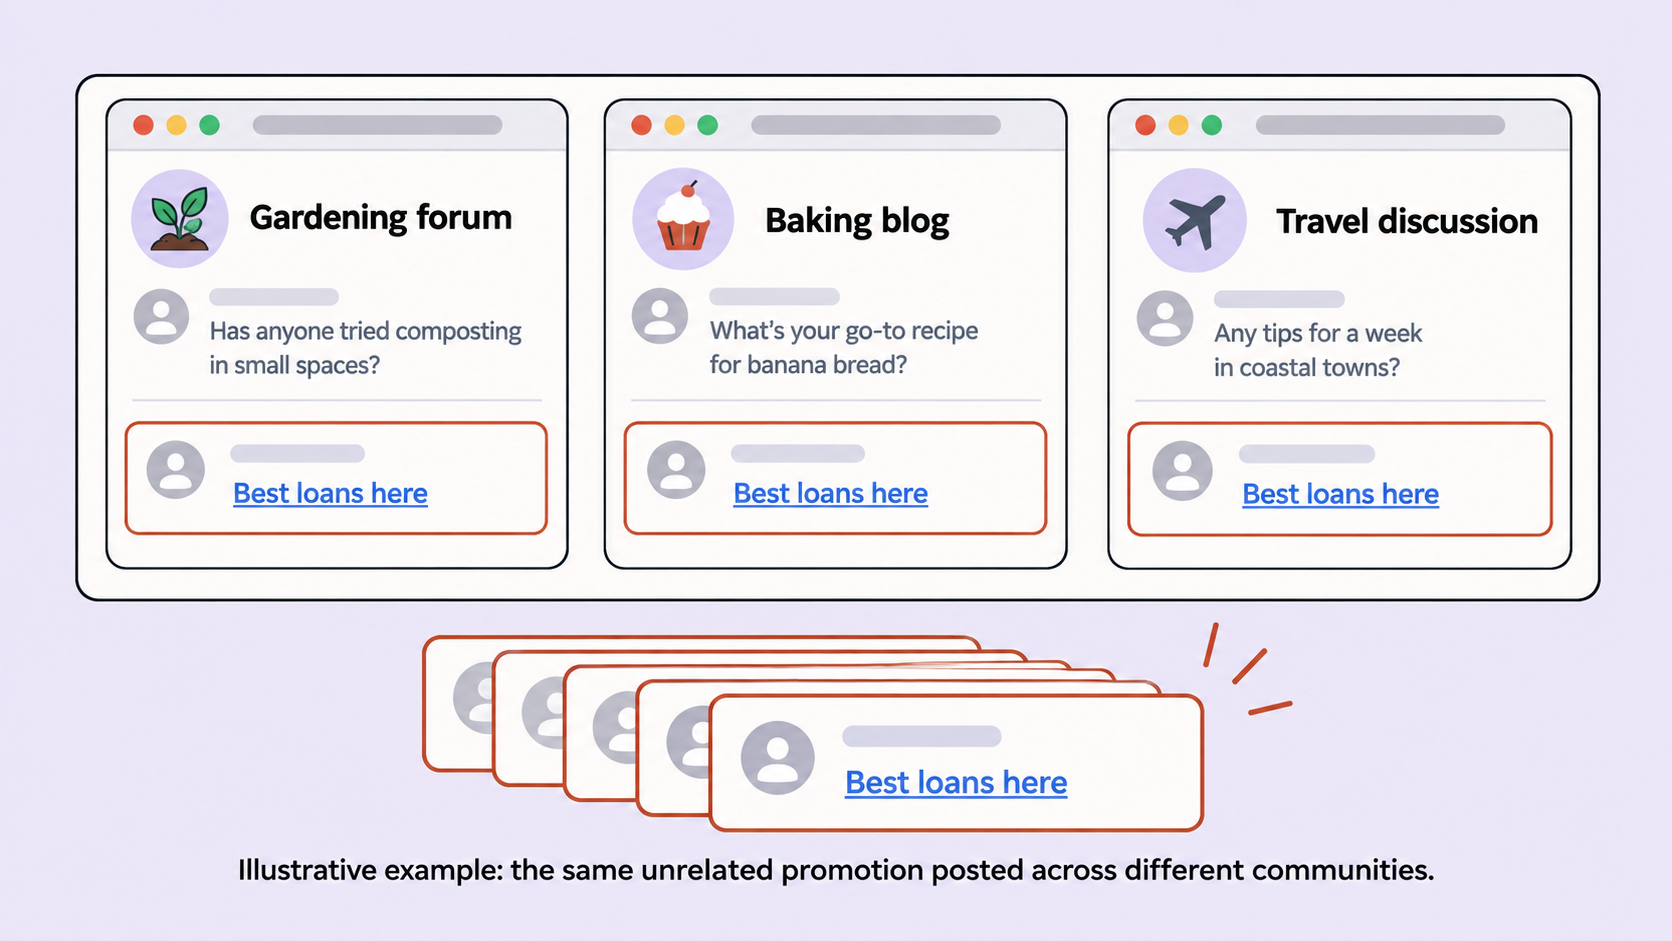
These packages promise large numbers of links by submitting comments, profiles or directory entries at volume. The variety of destinations can make a spreadsheet look impressive while saying little about the value of any placement.
Google’s comment-spam guidance describes unrelated comments and commercial usernames used to manufacture backlinks. It also explains why those links can be devalued.
Ask the supplier to open ten delivered URLs with you. Does the contribution make sense? Would the community welcome it? Is there a relevant, moderated listing a customer might use? A genuine trade directory and a bulk-submission package should not be treated as interchangeable.
Stop automated submissions you commissioned and document the placements. Review removal or correction where appropriate. Do not assume that every unsolicited link in your backlink report was created by your agency, or that every one requires a disavowal.
17. Manipulative widget, footer and template links
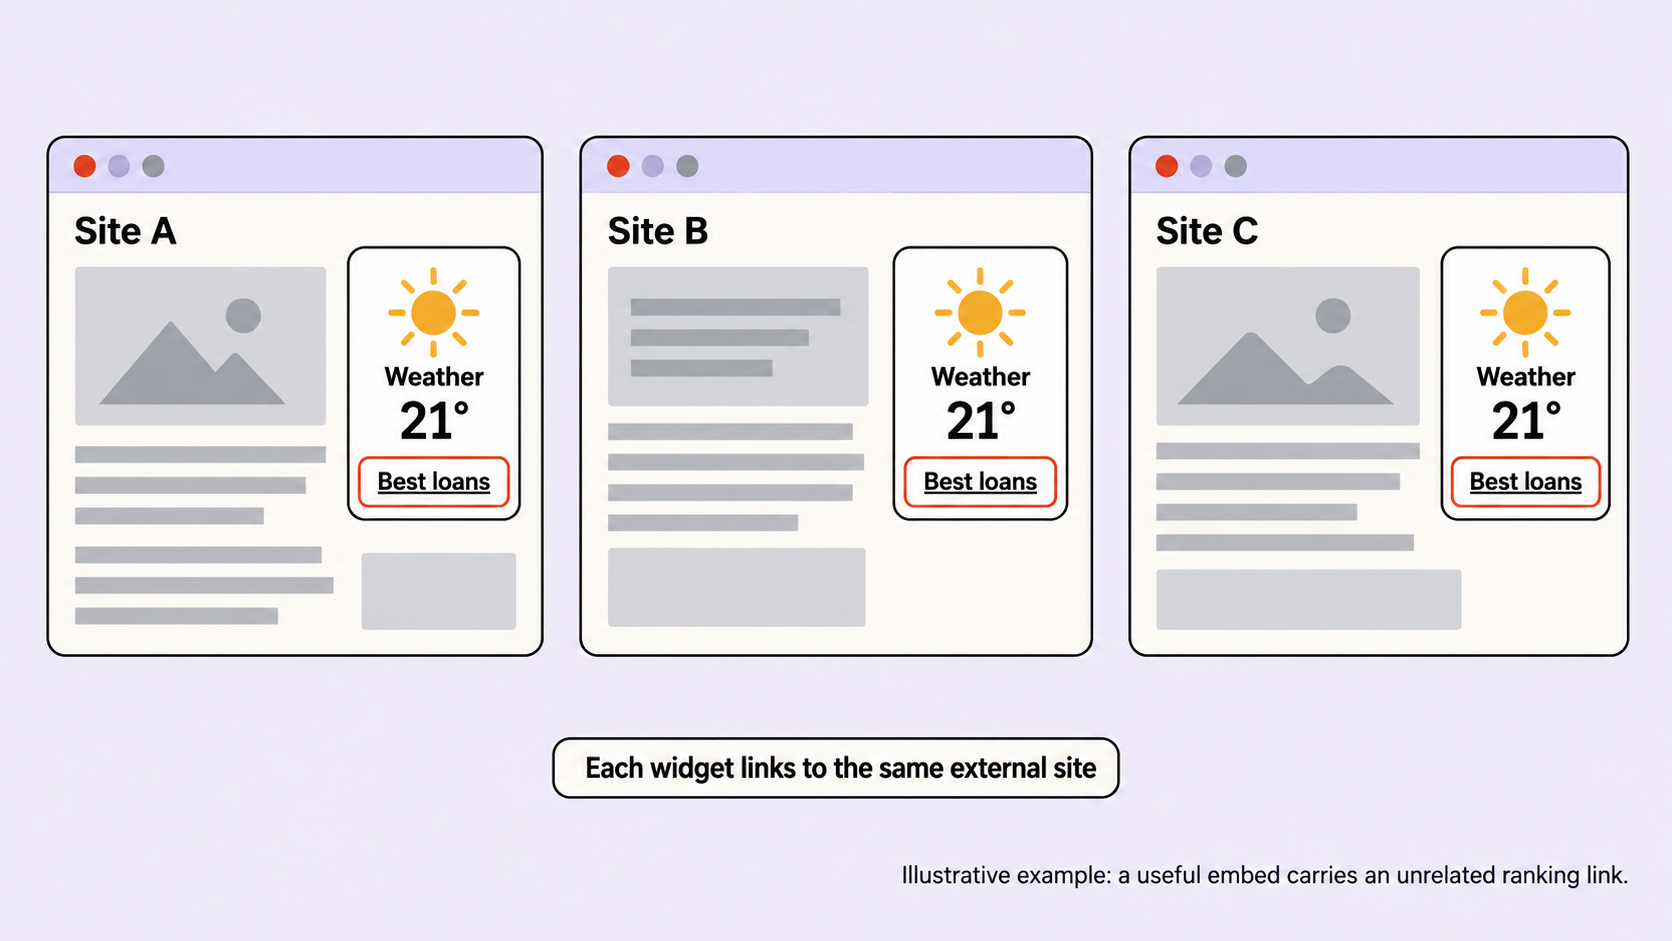
A free widget or website theme can distribute more than its useful feature. It can also carry a keyword-heavy link across the sites that install it, sometimes with little control left to the owner.
Google’s widget-link guidance specifically addresses non-editorial links embedded in distributed widgets. It recommends removing the offending links or preventing them from passing ranking credit.
Inspect what the installed component actually outputs. A weather widget should not quietly make your business a reference for an unrelated commercial service. Ask the vendor whether the link can be removed or qualified and whether updates restore it.
An ordinary navigational footer is not automatically suspicious. The concern here is the deliberate distribution of manipulative links, including arrangements that force an SEO link into a template. Fix the source component as well as individual pages, or the next update may undo the cleanup.
18. Fake tools and misleading functionality
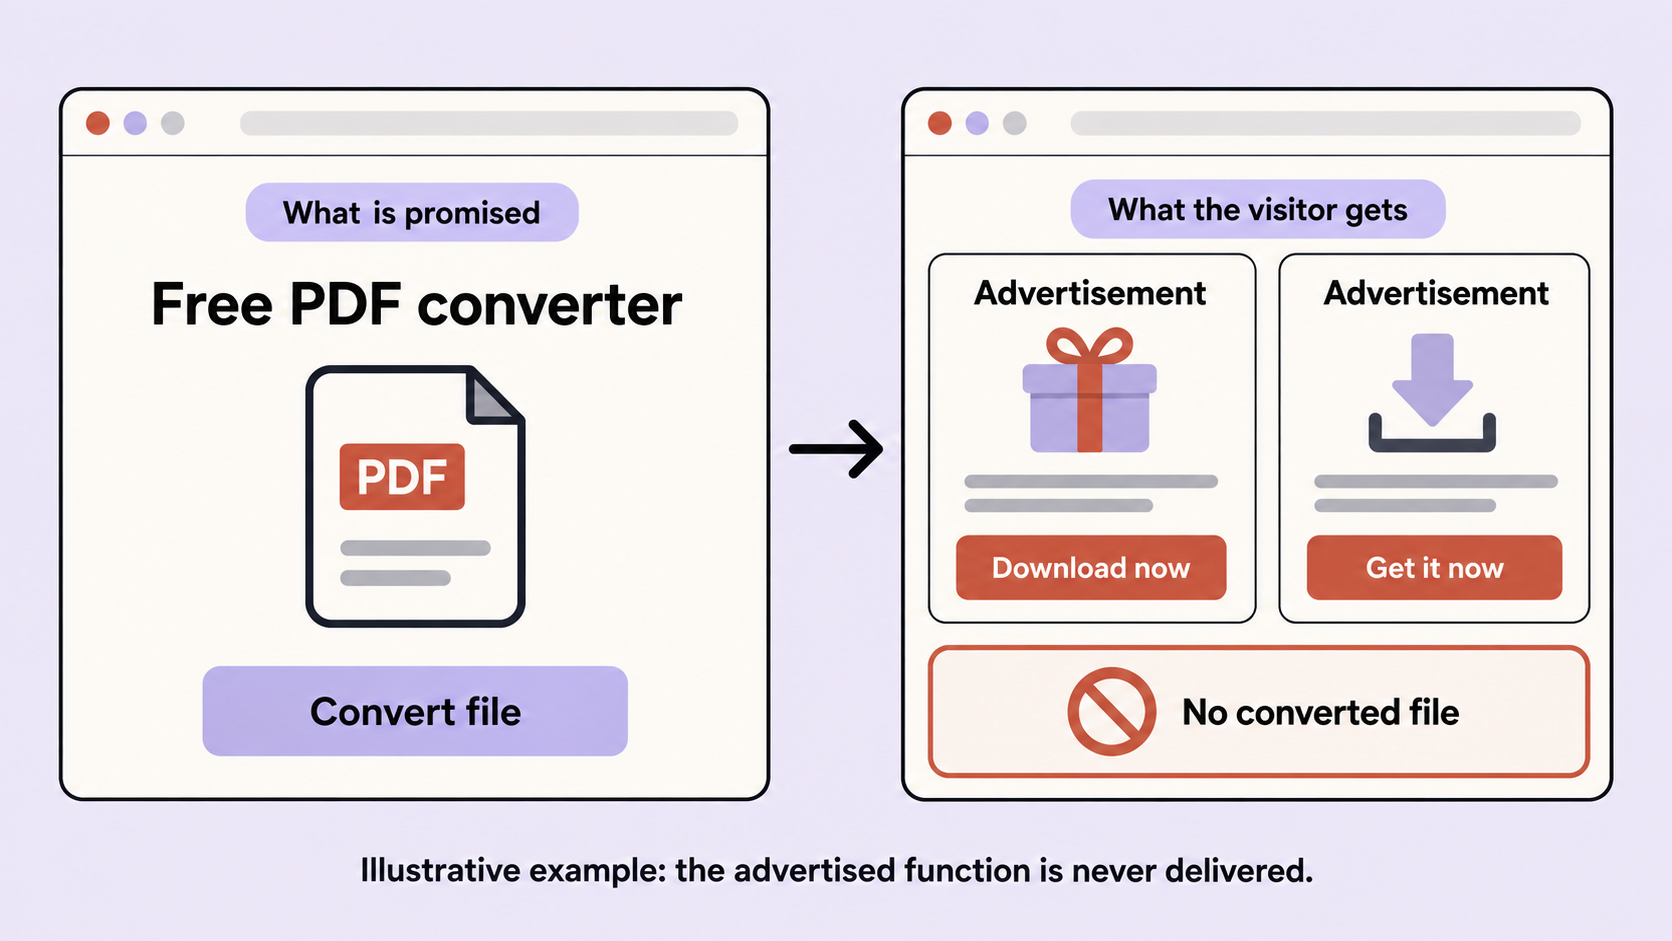
A page that promises a useful tool but mainly leads visitors through deceptive advertisements has a basic product problem. Google lists misleading functionality among its spam practices.
Test a hypothetical “free file converter” as a customer would. Can you complete the advertised task? Do the buttons perform the actions their labels describe? Is a price or sign-up requirement disclosed before the user invests time or submits a file?
Advertising, subscriptions and lead generation can fund real services. What I would reject is an SEO landing page whose claimed feature exists only to get the click. Build the functionality, state the conditions clearly and measure whether people complete the task. Calling a dead end a funnel does not improve it.
19. Hidden text and concealed links
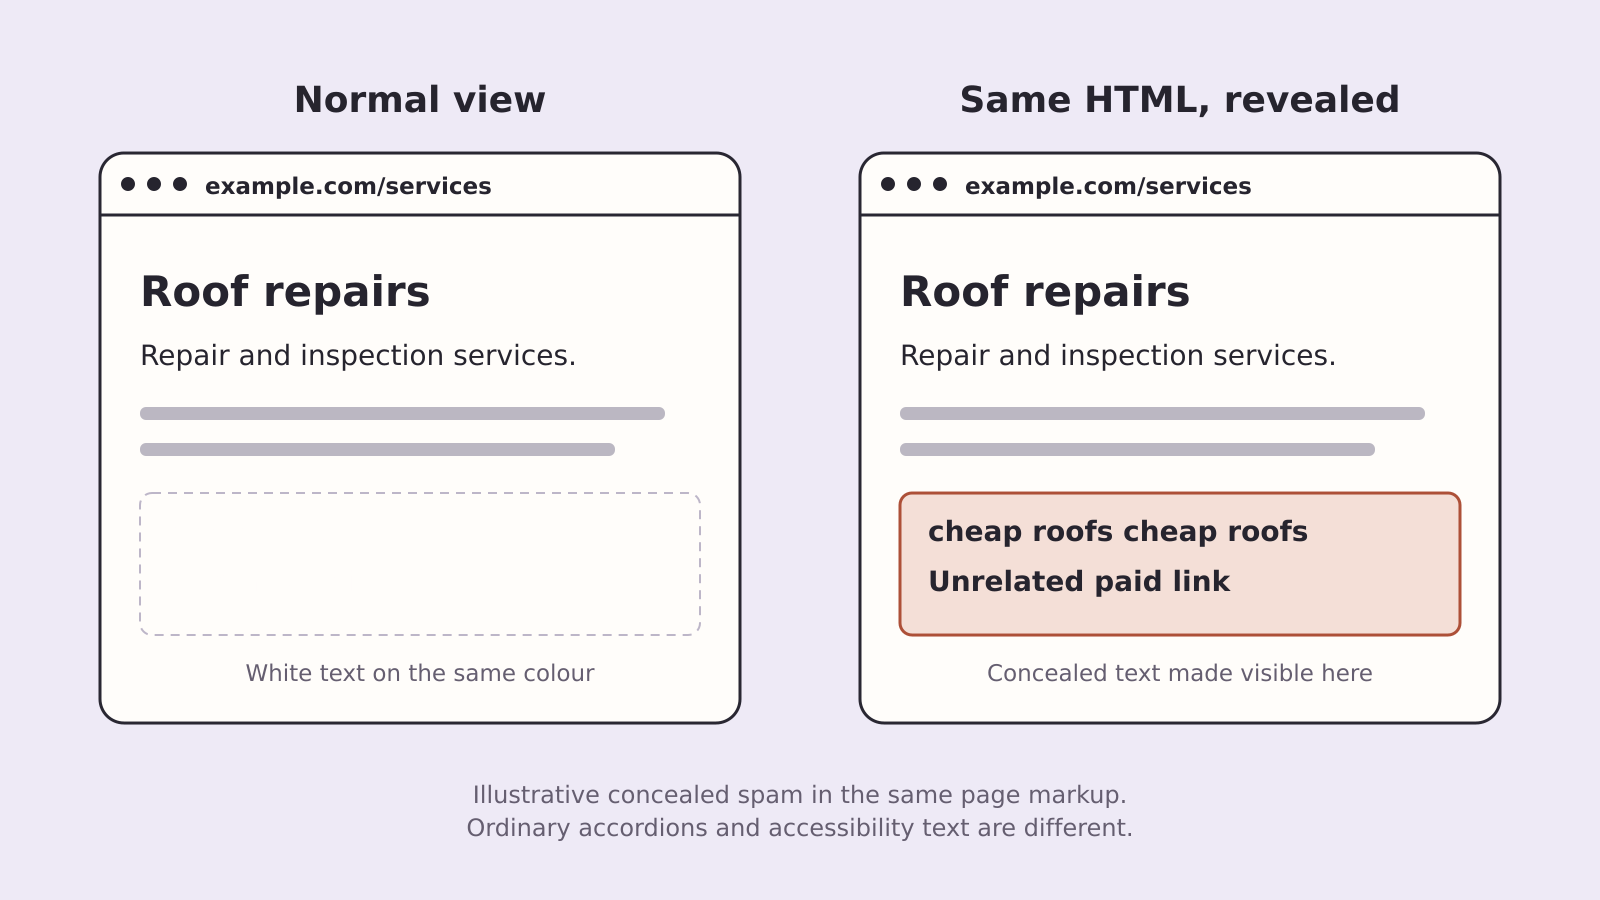
This involves concealing ranking-oriented text or links from ordinary visitors. It is distinct from a usable interface that expands content when someone asks to see it. Google’s hidden-content policy recognises legitimate uses such as accordions and screen-reader text.
Inspect the template when a supplier says that additional keyword copy will be “visible only to search engines.” Ask what benefit that material gives a visitor and why it needs to be hidden.
I would ask the same questions about concealed instructions intended to influence AI answers. A claim that “AI needs a secret version” should not survive scrutiny. Google’s AI-search guidance applies the existing search policies and says no special AI files or markup are needed for inclusion. That does not validate a supplier’s claimed manipulation technique.
Be careful with the correction. A developer should distinguish concealed spam from accessibility features, menus and other intentional interface behaviour. Removing every visually hidden element is an excellent way to create a second problem while fixing the first.
20. Keyword stuffing
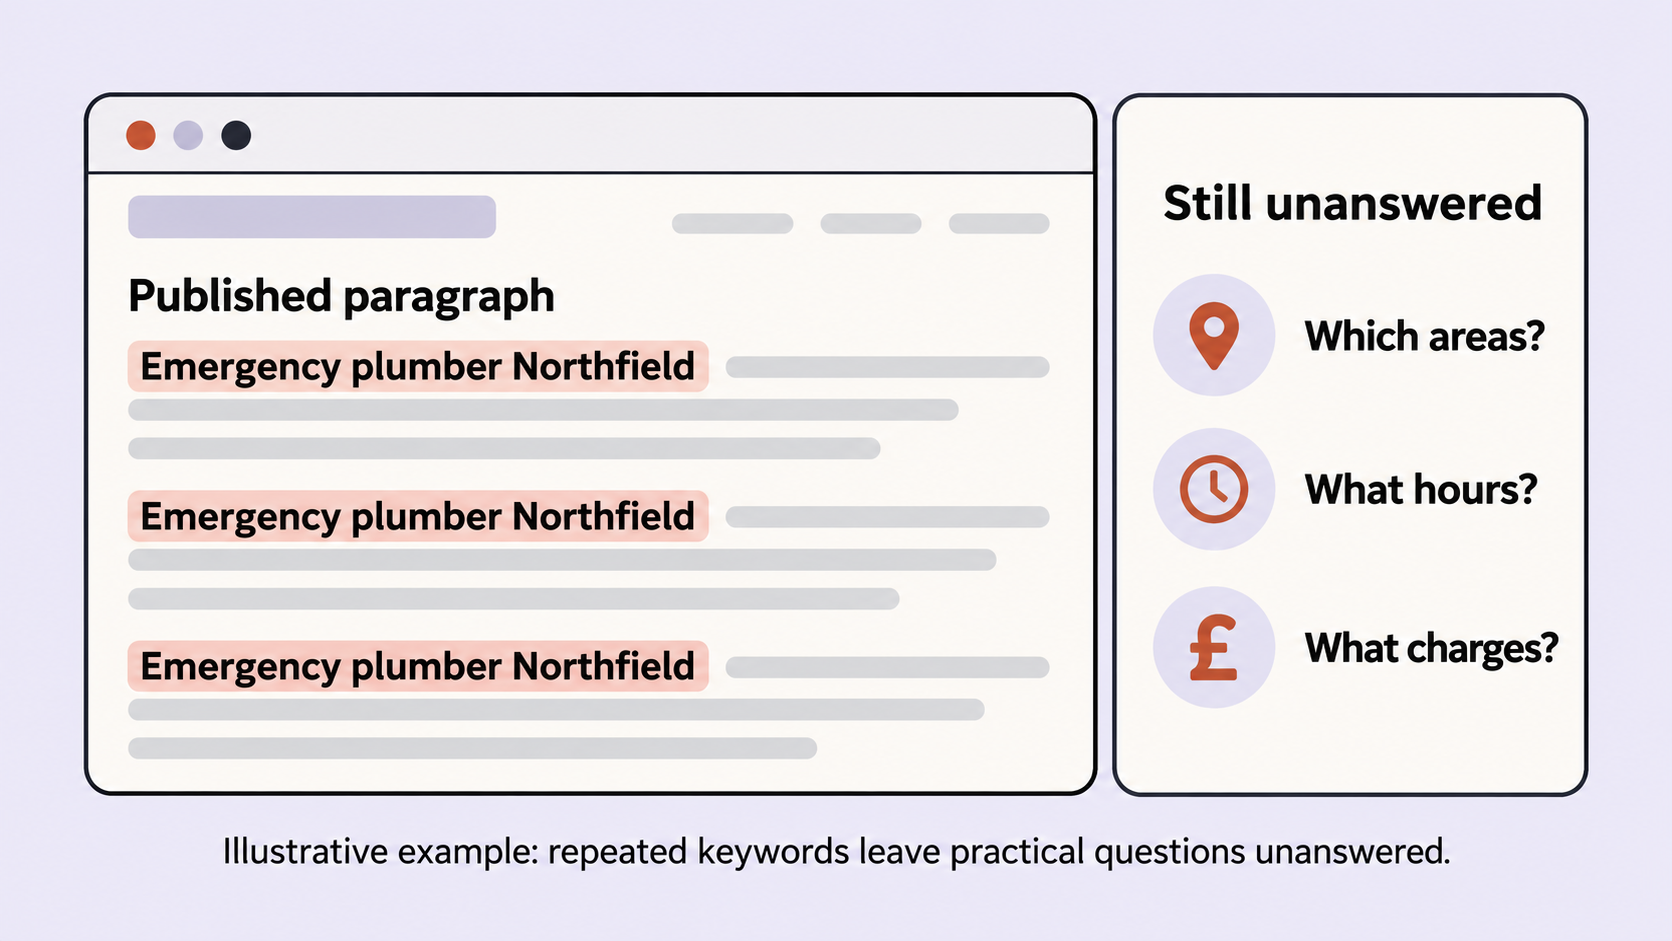
Keyword stuffing makes repetition do the work that useful information should do. Google’s SEO Starter Guide warns against excessive repetition, including variations of the same words.
An illustrative example is a paragraph that says “emergency plumber Northfield” repeatedly while failing to explain the call-out area, opening hours, charges or services. Each of those facts would help the customer more than another repetition.
Read the copy aloud, including titles, headings and image descriptions. Ask an editor to replace unnecessary repetitions with the information the page needs. A keyword-density target cannot decide whether the paragraph is useful. The same phrase may naturally recur in a technical explanation; intent, context and readability matter.
21. Deceptive structured data and invented ratings
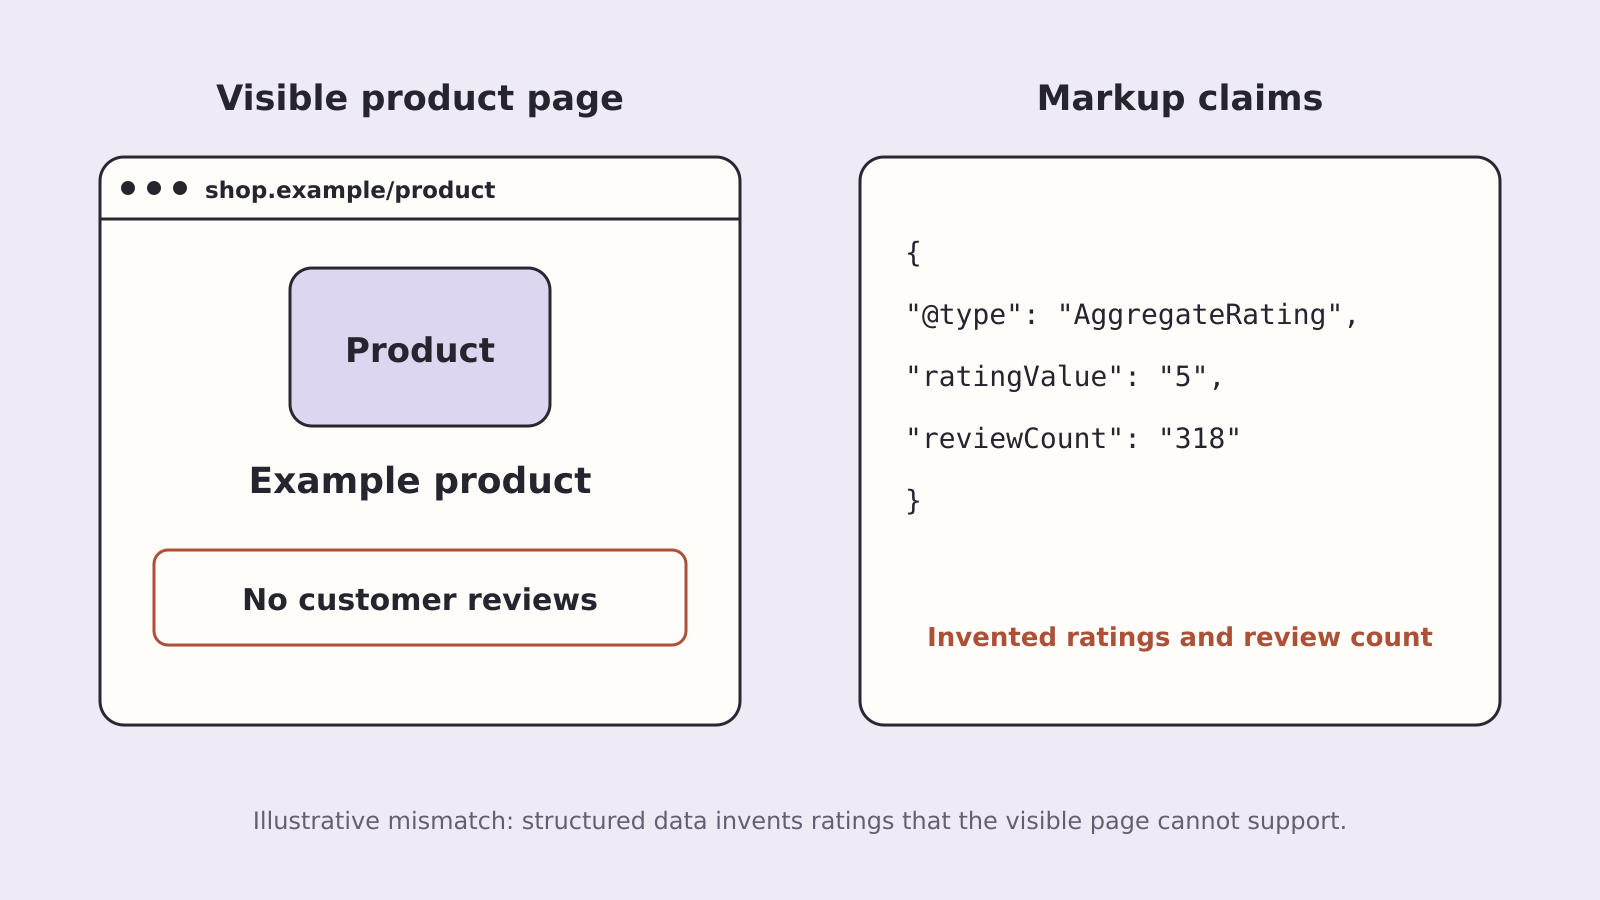
Structured data describes a page for machines. It should not invent reviews, products, jobs or events that the page does not actually support.
There is a precise consequence worth understanding. Google’s structured-data guidelines say a structured-data manual action removes eligibility for rich results; that action itself does not change the page’s ordinary web-search ranking. Other violations can still have their own consequences.
Compare the markup with the visible page and underlying records. Where did the rating come from? Does the job exist? Does the event have a real date and venue? A technically valid object can still contain false information.
Correct the data and the process that generated it. Passing a validator establishes neither factual accuracy nor a guarantee that Google will display a particular search feature.
22. Click bots and fabricated search engagement
Some services sell scripted searches, clicks or visits as a way to influence rankings. Google’s machine-generated traffic policy prohibits automated queries without express permission. That rule does not prove a vendor’s claimed ranking mechanism works.
I would want controlled evidence before believing a before-and-after chart. What else changed? Was there a comparison group? Did the visitors have any interest in the business? This research did not establish a dependable uplift or a standard penalty outcome for such a service.
The immediate commercial objection is simpler: paying to manufacture activity can corrupt the numbers used to judge the campaign. Separate suspected automated activity from actual enquiries and sales. Buy distribution to real people with a relevant need; do not let a purchased traffic total stand in for customers.
I want SEO work that leaves a website in better shape: useful pages, accurate information and links that make sense to readers. If a tactic depends on deception, fabricated reviews or a method your supplier refuses to explain, leave it alone. The agency’s contract may end, but the website and any cleanup remain your responsibility.
The post 22 black hat SEO techniques to avoid, ranked by potential damage appeared first on Search Engine Watch.
Source:: searchenginewatch.com